行业动态
x.com ·
@omarsar0
技术报告提出 Recurrent Looped Transformer:将循环扩展到 token 维度
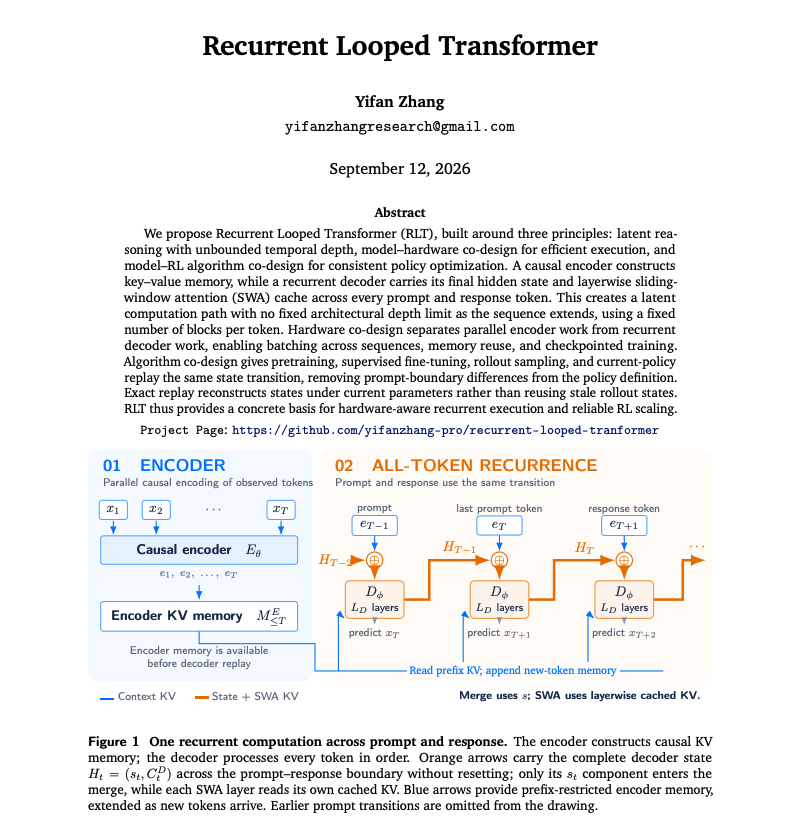
一份技术报告提出 Recurrent Looped Transformer(RLT),让解码器对每个 token(包括 prompt 和 response)递归:因果编码器构建全局 KV 记忆,每个新 token 结合编码器表示、上一 token 的最终隐状态和近期激活的滑动窗口缓存。48 层解码器下,t 个 token 的计算路径经过 48t 个解码块,单 token 成本保持不变,深度随序列增长。同一状态转移用于预训练、SFT、采样和 RL replay,prompt-response 边界不重置,RL replay 在当前权重下重建状态。作者称推理增益、硬件加速和 RL 扩展仍是目标,尚未测量。
AI推荐理由 该帖介绍了一份关于 Recurrent Looped Transformer(RLT)的技术报告:将循环结构扩展到 token 维度,解码器对每个 token(含 prompt 与 response)递归,因果编码器构建全局 KV 记忆,每步结合编码器表示、上一 token 的最终隐状态与滑动窗口缓存;48 层解码器下 t 个 token 的计算路径经过 48t 个解码块,而单 token 成本固定,深度随序列增长。同一状态转移用于预训练、SFT、采样与 RL replay,prompt-response 边界不重置,RL replay 在当前权重下重建状态。信息密度较高且给出了论文链接,但作者明确表示推理增益、硬件加速与 RL 扩展均尚未测量,属于设计提案而非已验证结果,故质量与兴趣分不宜过高。
62
浏览 1,015
点赞 12
评论 4
转发 2
正文
Looped transformers are a popular architecture topic right now.
This new technical report extends the loop across tokens.
Recurrent Looped Transformer (RLT) makes the decoder recurrent over every token, prompt and response included.
A causal encoder builds global KV memory. For each new token, the decoder combines the token's encoder representation with its own final hidden state from the previous token and a sliding-window cache of recent activations.
With a 48-layer decoder, the computation path after t tokens runs through 48t decoder blocks, while each token still executes a fixed number of blocks. Depth grows with the sequence and per-token cost stays the same.
The same state transition is used for pretraining, SFT, sampling and RL replay, and nothing resets at the prompt-response boundary. RL replay rebuilds states under the current weights instead of reusing stale rollout states.
The report is a design proposal. The author states that reasoning gains, hardware speedups and RL scaling are goals that have not been measured yet.
Paper: [github.com/yifanzhang-pro…](https://github.com/yifanzhang-pro/recurrent-looped-tranformer)
Chat with Paper: [academy.dair.ai/papers/recurre…](https://academy.dair.ai/papers/recurrent-looped-transformer)