大模型
x.com ·
@lmarena.ai(@lmarena_ai)
LMArena 研究:AI 评判模型存在自偏好,与人类判断差异显著
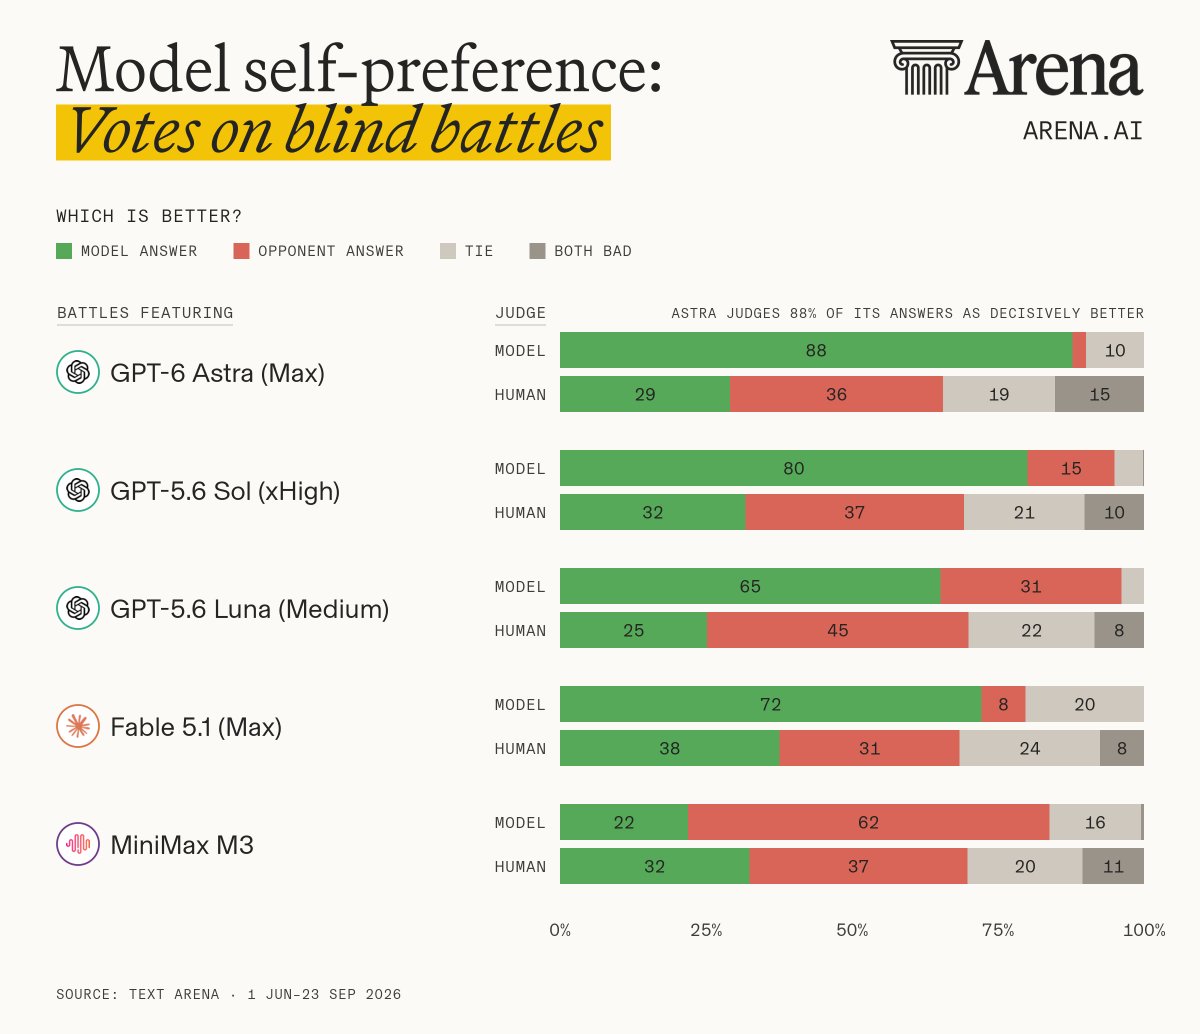
LMArena 对比 12 个模型在 Arena 上 1,460 场对战中的 34,580 条评判与人类投票,发现 AI 评判者偏好自身答案(平均 58% 选择自己,人类仅 34% 选择同一答案,GPT-6 Astra 自选率达 88%);人类在 32% 对战中判平局或双方皆差,而 GPT-5.6 Sol 有 96% 的情况选出胜者;AI 之间一致率为 79%,与人类一致率仅 57%,每个评判模型均存在 18 至 27 个百分点的差距。
AI推荐理由 LMArena 官方发布基于 34,580 条模型评判与 1,460 场人类投票对比的实证研究,给出模型自偏好、少判平局、AI 之间一致性高于与人类一致性等具体量化结论,数据明确、方法可追溯,对 LLM 评测与对齐研究有实际价值。
78
正文
Ask an AI model to pick the better answer, and it'll usually pick its own.
We compared 34,580 verdicts from 12 models with human votes across 1,460 battles on Arena. The results show that AI judges have their own taste, and it's unlike ours.
They:
- Favor their own answers. On average, a model picked its own answer 58% of the time. People picked that same answer 34% of the time. GPT-6 Astra picked itself 88% of the time.
- Rarely call a draw. People called a tie or "both bad" in 32% of battles. GPT-5.6 Sol picked a winner 96% of the time.
- Side with each other over people. They agreed with other AIs 79% of the time and with people 57% of the time. Every judge did, by a margin of 18 to 27 percentage points.
Full results in the article from [@DawidGalarowicz](https://x.com/DawidGalarowicz) below.

Arena.ai@arena
[x.com/i/article/2104…](https://x.com/i/article/2104955648664584192)
[🔗 View Quoted Tweet](https://x.com/arena/status/2104965778613452895)
💬11🔄13❤️147👀13733📊24