智能体
x.com ·
@omarsar0
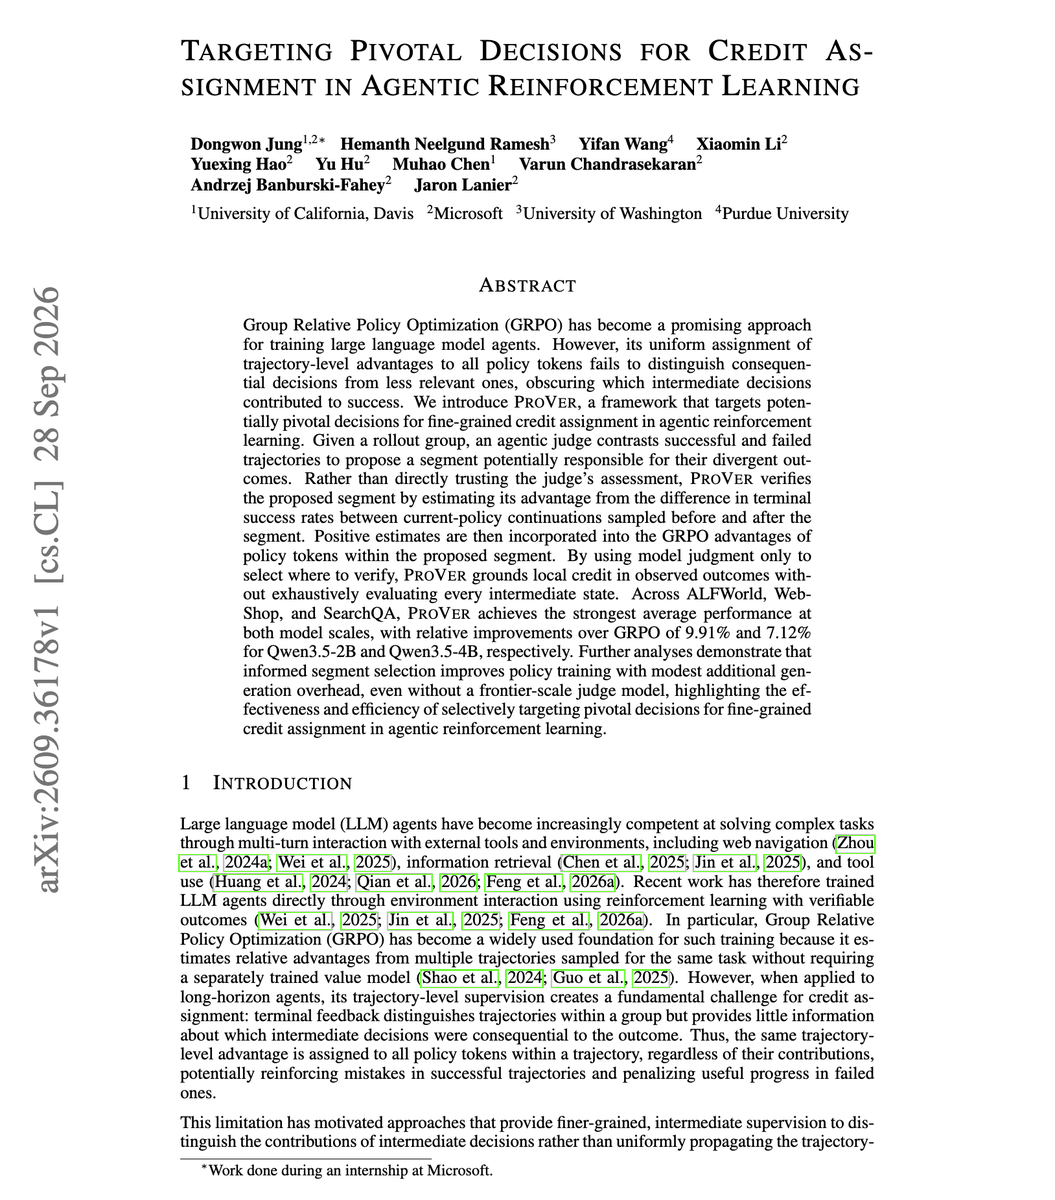
ProVer:用 LLM judge 定位关键片段改进 agent RL 信用分配
一条推文介绍 agent 强化学习信用分配论文 ProVer。其思路是让 LLM judge 对比成功与失败 rollout,指出造成差异的轨迹片段,再从该片段前后采样续写,用成功率变化作为该片段的 advantage,以解决 GRPO 对整条轨迹赋予相同 advantage、无法区分决定性步骤的问题。据称在 ALFWorld、WebShop、SearchQA 上相对 GRPO 提升 9.91%(Qwen3.5-2B)和 7.12%(Qwen3.5-4B),judge 换用更小模型仍有效,并附 arXiv 链接。
AI推荐理由 介绍 agent RL 信用分配论文 ProVer:用 LLM judge 定位轨迹中的关键片段,再用该片段前后续写的成功率变化作为其 advantage,以弥补 GRPO 对整条轨迹统一 advantage 的缺陷。给出 ALFWorld、WebShop、SearchQA 上相对 GRPO 的提升数字(Qwen3.5-2B 9.91%、4B 7.12%)及 arXiv 链接,属可追溯的研究转述,但数据来自转述而非原文核验。
78
浏览 516
点赞 0
评论 1
转发 0
正文
Good paper on credit assignment for agent RL.
The main finding is that you want an LLM judge to choose where to check a trajectory, and the rollouts to decide how much credit that step gets.
GRPO gives every token in a trajectory the same advantage, so the training signal cannot tell the decisive step from the rest.
ProVer has a judge compare successful and failed rollouts and name the segment it thinks caused the difference. It then samples continuations from just before and just after that segment and uses the change in success rate as the segment's advantage.
Across ALFWorld, WebShop and SearchQA, this gives relative improvements over GRPO of 9.91% for Qwen3.5-2B and 7.12% for Qwen3.5-4B. It still helps when the judge is a smaller model.
Paper: [arxiv.org/abs/2609.36178](https://arxiv.org/abs/2609.36178)
Chat with Paper: [academy.dair.ai/papers/targeti…](https://academy.dair.ai/papers/targeting-pivotal-decisions-for-credit-assignment-in-agentic-reinforcement-learn-2609.36178)