最新资讯
reddit.com OpenAI 称 Astra 仅满足 10% 安全任务标准 dev.to FreeToken:在自有 GPU 上运行前沿 MoE 模型及其内存需求 dev.to 当 AI Agent 说“完成”时,究竟完成了什么? dev.to 部署 Underdog Bark 3.0 Pro:逐字转写、自定义后端与分块设置 dev.to 为艰难对话构建 AI:五个 Agent、一条安全正则与一位盲评监督者 techcrunch.com Palo Alto Networks 洽谈以 5 亿美元收购 AI Agent 安全初创公司 Clutch theinformation.com 黄仁勋被要求就涉华间谍指控向国会作简报 www.infoq.com Edera 推出 Object Capability Bounded Authority,试图将凭证与 AI Agent 工作负载隔离 wechat 这波杀疯了!旗舰级模型不限量、1个月视频额度免费领 bloomberg.com AI 抛售蔓延至信用市场,软银领跌亚洲美元债 dev.to 如何在专用 GPU 服务器上用 OpenAI 兼容 API 部署 LLM dev.to 审计 153 份 Claude Code 与 Codex 会话记录:User-Agent 与 URL 中的邮箱泄露
多元动态
登录 注册
智能体 x.com · @omarsar0

Meta 等提出 Context Language Models:让模型原生读写自身上下文

原文 我的收藏

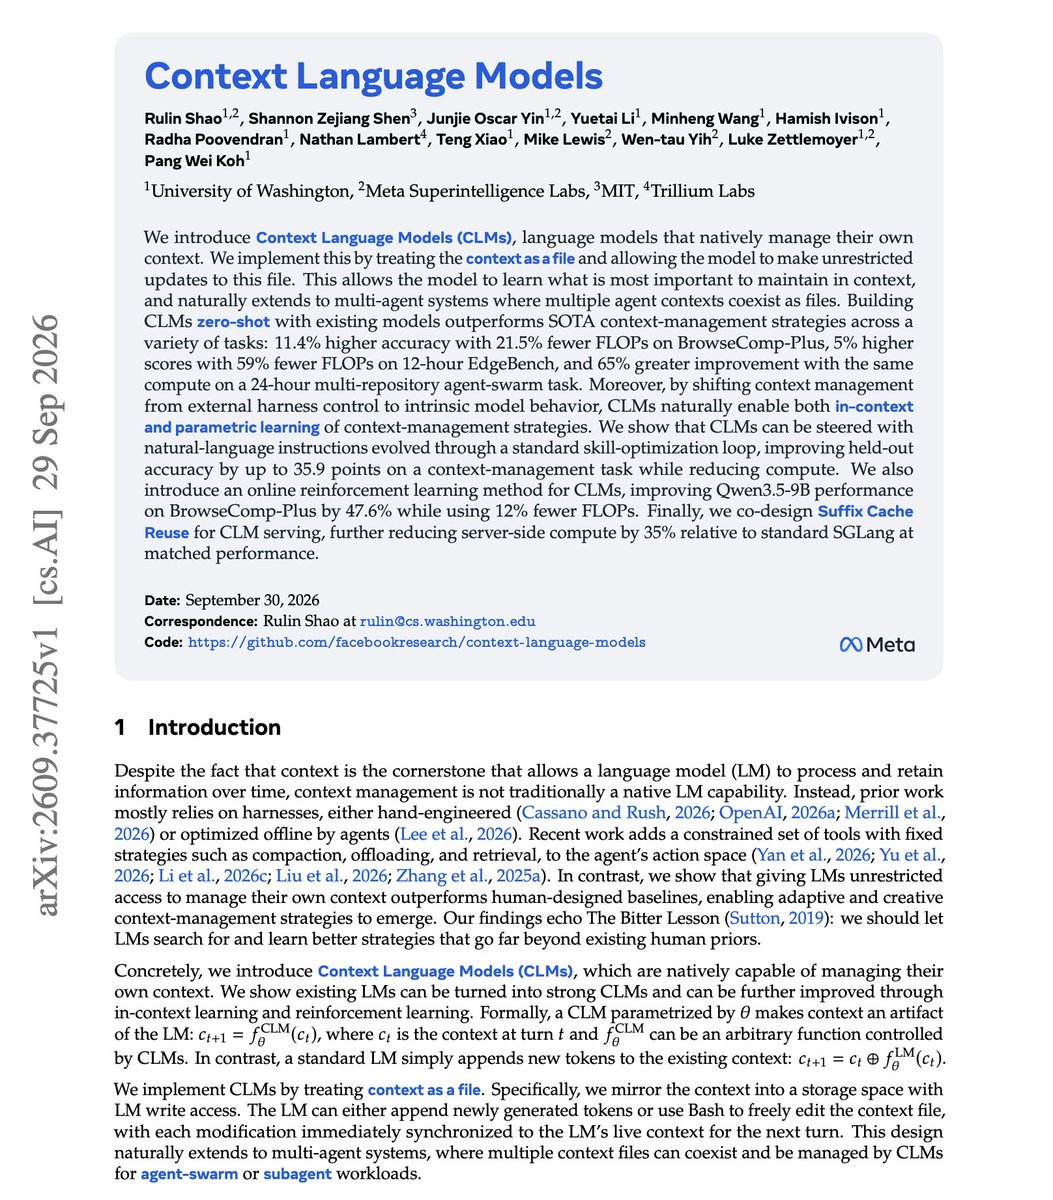
elvis 转述一篇据称来自 Meta 及合作者的论文,研究让语言模型原生管理自身上下文:Context Language Models 将上下文作为文件,由模型用 Bash 编辑,自行决定保留、重写或删除内容,与 RLM 的区别在于 CLM 暴露可读写的实时上下文(含执行中累积的信息)。转述称零样本在 BrowseComp-Plus 上准确率提升 11.4%、FLOPs 减少 21.5%;在跨六个仓库、24 小时的多 agent 任务中同算力下提升 65%;在线 RL 使 Qwen3.5-9B 在 BrowseComp-Plus 上提升 47.6% 且 FLOPs 减少 12%;针对上下文中部编辑破坏前缀缓存的问题,作者提出 Suffix Cache Reuse,称较标准 SGLang 降低服务器算力 35%。上述数据来自转述,需以论文原文核实。

AI推荐理由 转述一篇据称来自 Meta 及合作者的论文,主题是让语言模型原生管理自身上下文(Context Language Models,将上下文作为可用 Bash 编辑的文件),并给出与 RLM 的差异说明及多项量化结果(BrowseComp-Plus 上零样本准确率提升 11.4%、FLOPs 减少 21.5%;24 小时多仓库 agent 任务同算力下提升 65%;在线 RL 使 Qwen3.5-9B 提升 47.6% 且 FLOPs 减少 12%;Suffix Cache Reuse 降低服务器算力 35%)。信息密度高、涉及 Agent 上下文管理与训练方法,对 Agent 与模型工程有参考价值;但数据均来自转述,未提供独立验证,论文链接指向第三方 academy 页面,需以原文核实。

78 浏览 9,824 点赞 129 评论 18 转发 15

正文

Banger paper from Meta and colleagues. (bookmark it) They discuss benefits of giving your agent write access to its own context. In other words, they investigate how effective it is to allow a language model to natively manage its context. Context Language Models keep the context as a file the model edits with Bash, so the model decides what to keep, rewrite or remove. It's a bit different from RLM, for those who are wondering but it pulls an interesting theme. RLMs place a large input in an external variable that the model can read and process recursively, but they do not let the model directly edit its own live interaction context. CLMs instead expose the live context as a read-write file, including information accumulated during execution. Applied zero-shot, this gets 11.4% higher accuracy with 21.5% fewer FLOPs on BrowseComp-Plus than existing context-management strategies. On a 24-hour task where a swarm of agents works across six repositories, it gets 65% more improvement for the same compute. The strategy can also be trained. Online RL improves Qwen3.5-9B on BrowseComp-Plus by 47.6% while using 12% fewer FLOPs. Edits in the middle of the context break prefix caching, so the authors add Suffix Cache Reuse, which cuts server compute by 35% against standard SGLang. Paper: [academy.dair.ai/papers/context…](https://academy.dair.ai/papers/context-language-models-2609.37725) ![Tweet Image](https://pbs.twimg.com/media/HTjqUFvbEAAp7b9.jpg)
来源报道 · 1 篇 · 以下链接均前往原始媒体

← 返回精选动态 原文

更多内容