大模型
x.com ·
@jerryjliu0
LlamaIndex 评测:Astra 在表格密集文档解析达 93.2%,但成本与长文档仍是短板
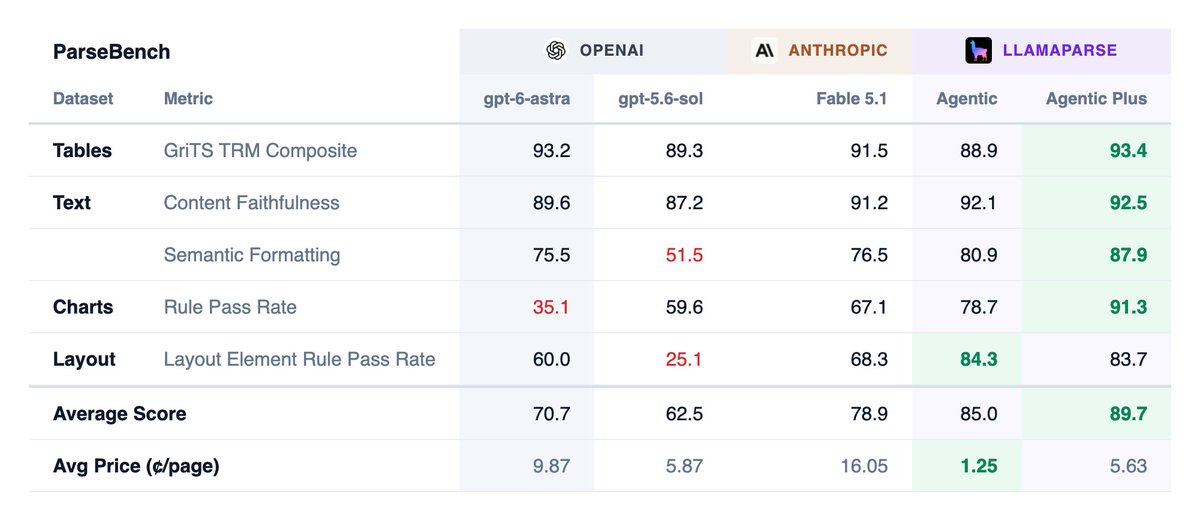
Jerry Liu 称 Astra 是其测试过解析含表格复杂文档最好的模型之一,在 ParseBench 上达到 93.2%,适合金融等表格密集文档的临时分析;但每页约 10 美分,不适合文档量大的 OCR 工作负载,图表任务上 Fable 5.1 表现更好。其引用的原推文补充:GPT-6 Astra 在短文档抽取上达 97.2%(新 SOTA)、中文档 90.6%,但长文档一次性抽取仅 31.7%,平均每页约 11 美分,是低成本方案约 10 倍;原生 OCR 相比其他前沿模型优势不大,表格理解强但图表、版式和语义格式较弱。
AI推荐理由 LlamaIndex 的 Jerry Liu 给出 Astra(GPT-6 Astra)在文档解析基准 ParseBench 上的具体数字:表格密集文档 93.2%,并指出每页 10 美分不适合文档量大的 OCR 场景、图表任务上 Fable 5.1 更好。引用的推文还给出短文档 97.2%、中文档 90.6%、长文档仅 31.7%、平均每页 11 美分等数据。属于厂商自建基准上的自报结果,需注意基准与利益相关性,但数据具体、含成本与局限说明,对文档抽取选型有参考价值。
70
浏览 754
点赞 5
评论 3
转发 0
正文
Astra is one of the best models we've tested at parsing complex documents with tables, at 93.2% on ParseBench.
So it seems well suited for ad-hoc analysis over table-heavy documents e.g. in finance.
To be fair, it's also at 10c per page so not suitable for document-heavy OCR workloads. Fable 5.1 still performs a better at charts.
Check out the full set of results on ParseBench: [parsebench.ai](https://www.parsebench.ai/)

Jerry Liu@jerryjliu0
We benchmarked GPT-6 Astra on hard document parsing and extraction tasks.
It is the best frontier model for one-shotting document extraction over short and medium-sized documents:
📊 97.2% over short documents, achieving a new SOTA on our benchmark
📊 90.6% over medium documents
But a few caveats:
\* it's pricy! The average price per page is 11c which is 10x our cost-effective document extraction solution
\* one-shot performance over long documents is inherently tricky, it only achieves 31.7%
\* the native OCR capabilities of Astra isn't that much better than other frontier models (e.g. Fable 5.1, gpt-5.6-sol). It does very well on table understanding, but isn't great on charts, layout, and semantic formatting.
Full results for document extraction on ExtractBench[extractbench.ai](https://www.extractbench.ai/)c3

[🔗 View Quoted Tweet](https://x.com/jerryjliu0/status/2096258549131165746)