智能体
x.com ·
@omarsar0
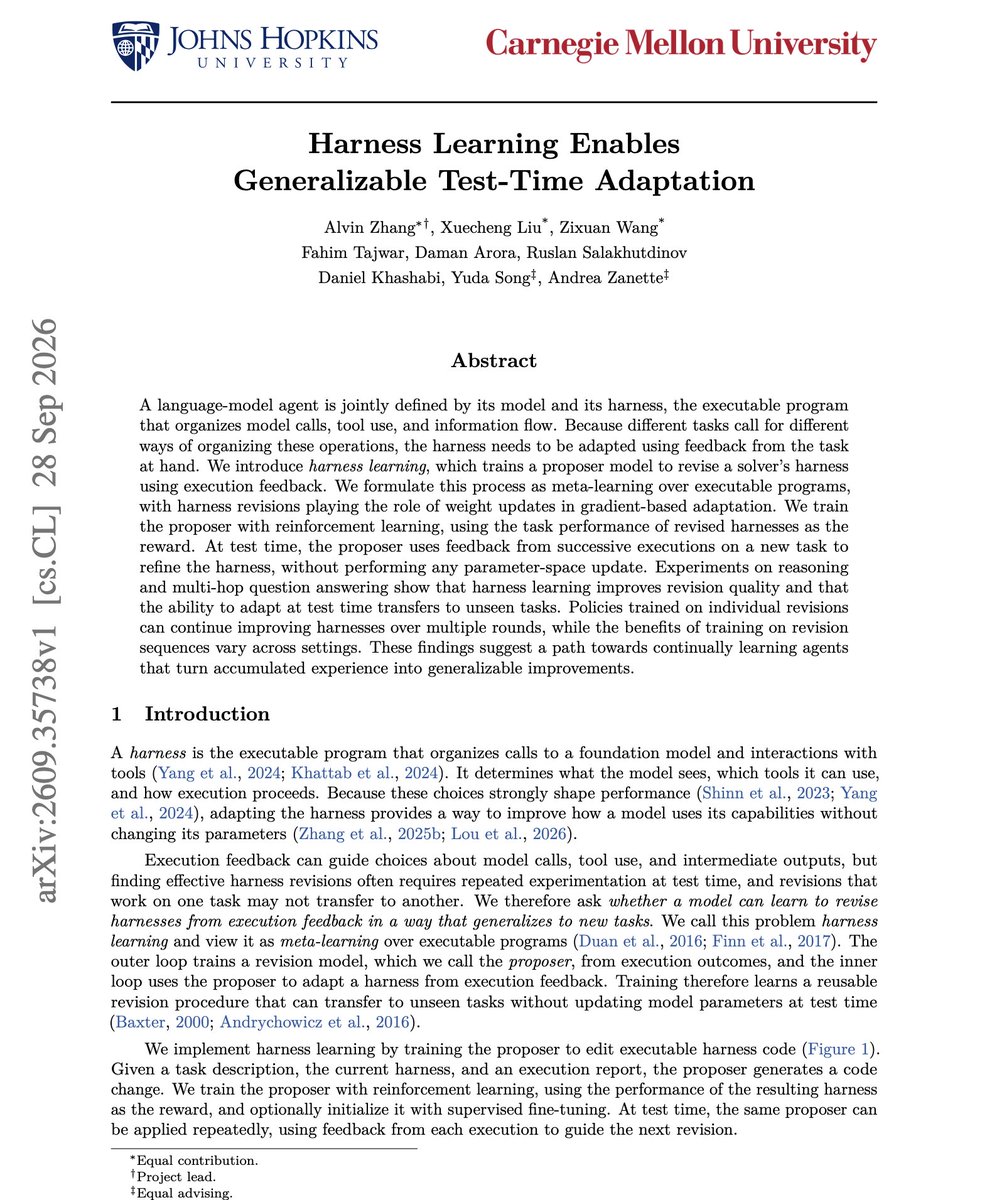
CMU 论文提出 harness learning:用 RL 改写 Agent 框架代码而非模型权重
一条 X 帖子介绍 CMU 关于 harness learning 的论文:用强化学习训练 proposer 模型,读取任务、当前 harness 与执行报告后输出对 harness 的代码修改,奖励为修改后 harness 的得分,solver 模型保持不变。帖中称,4B proposer 在 Reasoning Gym 的单步修订上超过其 35B 教师模型,并泛化到训练中未见过的任务族;在 HotpotQA 上训练的 proposer 在 MuSiQue 和 2WikiMultihopQA 上也能持续改进 harness。帖子附有 arXiv 链接。
AI推荐理由 帖子介绍一篇 CMU 关于 harness learning 的论文,核心思路是用 RL 训练 proposer 模型读取任务、当前 harness 和执行报告后直接改写 harness 代码,solver 模型权重不变,奖励为修改后 harness 的得分。帖中给出具体结果:4B proposer 在 Reasoning Gym 单步修订上超过其 35B 教师模型,且在未见过的任务族上有效;在 HotpotQA 上训练的 proposer 可迁移到 MuSiQue 和 2WikiMultihopQA。附有 arXiv 链接,可追溯,但为对论文的二手转述,未提供完整实验细节。
78
浏览 3,967
点赞 65
评论 14
转发 8
正文
Banger paper from CMU on harness learning.
(bookmark it)
Also, pay attention to this important new AI engineering skill of improving agents by editing their harness code instead of their weights.
Seeing a huge shift towards this.
The authors train a proposer model with RL to read a task, the current harness and an execution report, then write a code edit to the harness.
The reward is the score of the revised harness. The solver model never changes.
A trained 4B proposer beats its 35B teacher at single-step revision on Reasoning Gym, including task families it never saw in training. A proposer trained on HotpotQA keeps improving harnesses on MuSiQue and 2WikiMultihopQA.
Paper: [arxiv.org/abs/2609.35738](https://arxiv.org/abs/2609.35738)
Chat with Paper: [academy.dair.ai/papers/harness…](https://academy.dair.ai/papers/harness-learning-enables-generalizable-test-time-adaptation-2609.35738)