AI编码
x.com ·
@omarsar0
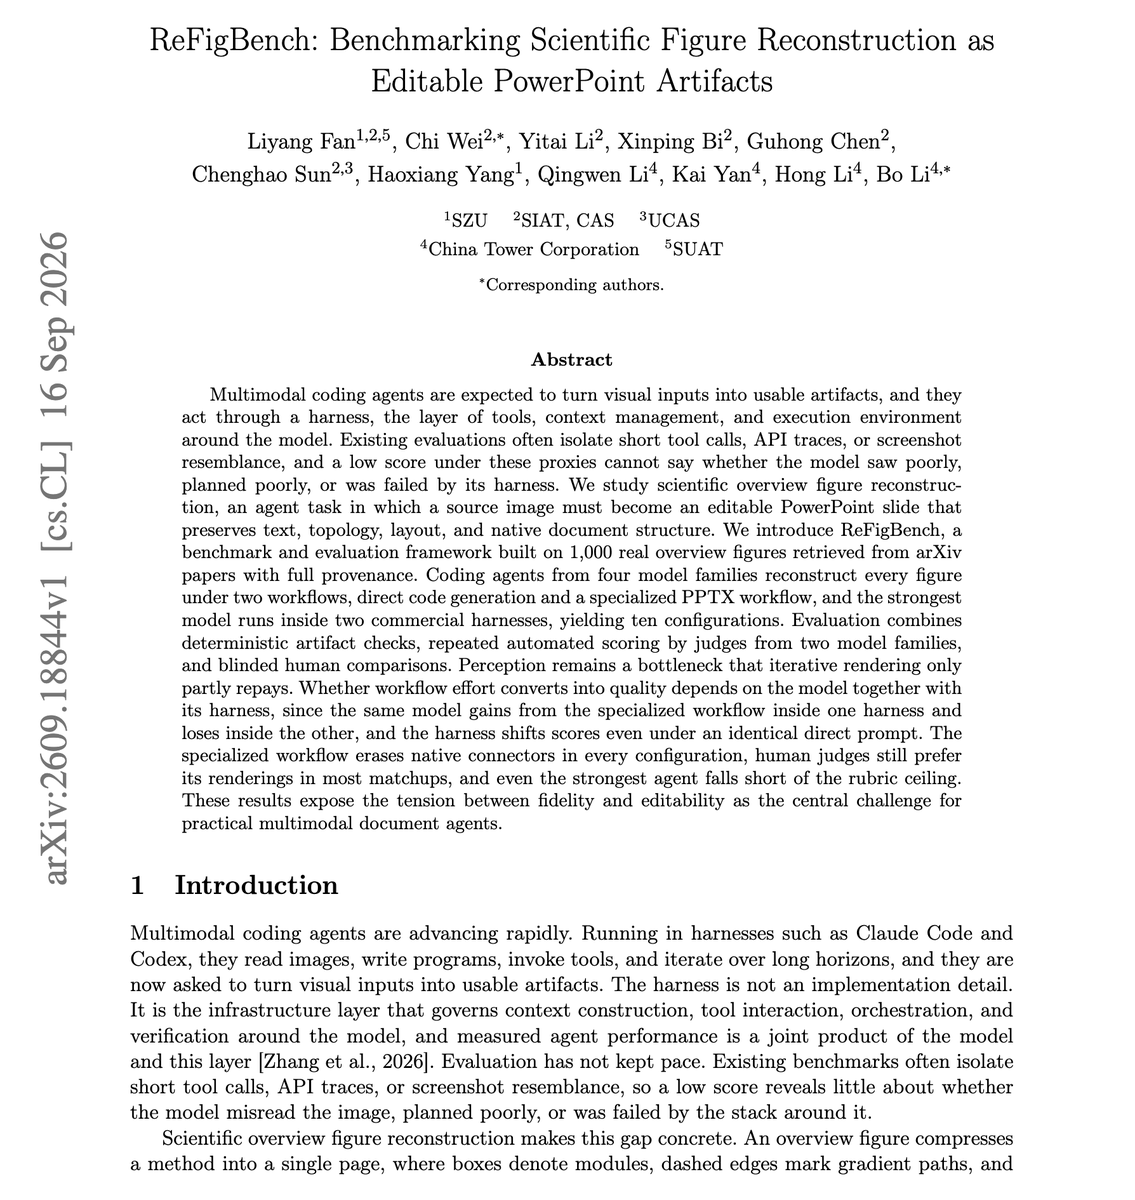
论文 ReFigBench:harness 显著影响编码 Agent 表现
研究者分享的 ReFigBench 论文显示,同一 1000 个任务下 GPT-5.5 在 Claude Code 与 Codex 两个 harness 中结果不同,专用 PowerPoint 工作流在一个 harness 中提升、在另一个中变差,提示词相同时 harness 也会改变得分。基准要求编码 Agent 将真实 arXiv 概览图重建为可编辑 PowerPoint,覆盖 GPT、Claude、MiMo、MiniMax 十种配置,由产物检查、两类 LLM 评委和盲测人工比较评分。作者指出感知仍是主要瓶颈:专用工作流在各配置中移除了原生连接线,但人工评委在多数对比中仍更偏好其渲染结果。
AI推荐理由 该帖介绍 ReFigBench 论文:在相同 1000 个任务上,GPT-5.5 在 Claude Code 与 Codex 两个 harness 中表现不同,专用 PowerPoint 工作流在一个 harness 中提升、在另一个中变差;覆盖 GPT、Claude、MiMo、MiniMax 十种配置,采用产物检查、两类 LLM 评委与盲测人工比较。指出 harness 对编码 Agent 结果影响显著、感知仍是主要瓶颈,对 Agent 评测与开发工具有直接参考价值。属研究者转述,需以论文原文为准。
78
浏览 1,769
点赞 24
评论 5
转发 3
正文
Impressive paper showing how much the harness changes a coding agent's results.
Harnesses do play a huge role in what you are getting out of the models.
GPT-5.5 was run inside both Claude Code and Codex on the same 1,000 tasks. With a specialized PowerPoint workflow, it improved inside one harness and got worse inside the other.
The harness also changed scores when the prompt was identical.
ReFigBench asks coding agents to rebuild real arXiv overview figures as editable PowerPoint slides that keep the text, layout and connections.
It covers ten configurations across the GPT, Claude, MiMo and MiniMax families, scored by artifact checks, two families of LLM judges and blinded human comparisons.
Perception is still the main bottleneck. The specialized workflow removed native connectors in every configuration, yet human judges still preferred its renderings in most matchups.
Paper: [arxiv.org/abs/2609.18844](https://arxiv.org/abs/2609.18844)
Chat with Paper: [academy.dair.ai/papers/refigbe…](https://academy.dair.ai/papers/refigbench-benchmarking-scientific-figure-reconstruction-as-editable-powerpoint-2609.18844)