最新资讯
dev.to 你的 Agent Harness 应具备的 17 项能力 dev.to 离线 AI 记忆中 0.8 余弦阈值为何失效 dev.to Kimi K3.1 Pro 开放权重:自托管 2.8T 模型前的开发者清单 dev.to 如何通过工具调用引导模型以提升 Harness 质量 dev.to AI Agent 审计轨迹不等于对话记录 dev.to 精简 MCP server 工具数量:更少工具、更小影响面,双重收益 dev.to 为什么 git checkout 无法撤销 AI 编码 agent 的改动? wechat AI短剧门槛降降降!实测即梦短剧工作室:剧本分镜预演一条龙,伙伴计划长期护航 dev.to 让模型改写文档前,先量化事实保真度 dev.to 回放 153 个 Claude Code 与 Codex 会话,审计 Agent 的生产影响范围 dev.to 银行 77 意图分类最便宜 LLM:GPT-6.1 Terra 每次成功任务 $0.000727 theinformation.com Chesky的副业:Airbnb向CEO新设AI实验室出售IP
多元动态
登录 注册
行业动态 website ·

Perplexity 公开搜索排序模型的 GPU serving 研究

原文 我的收藏

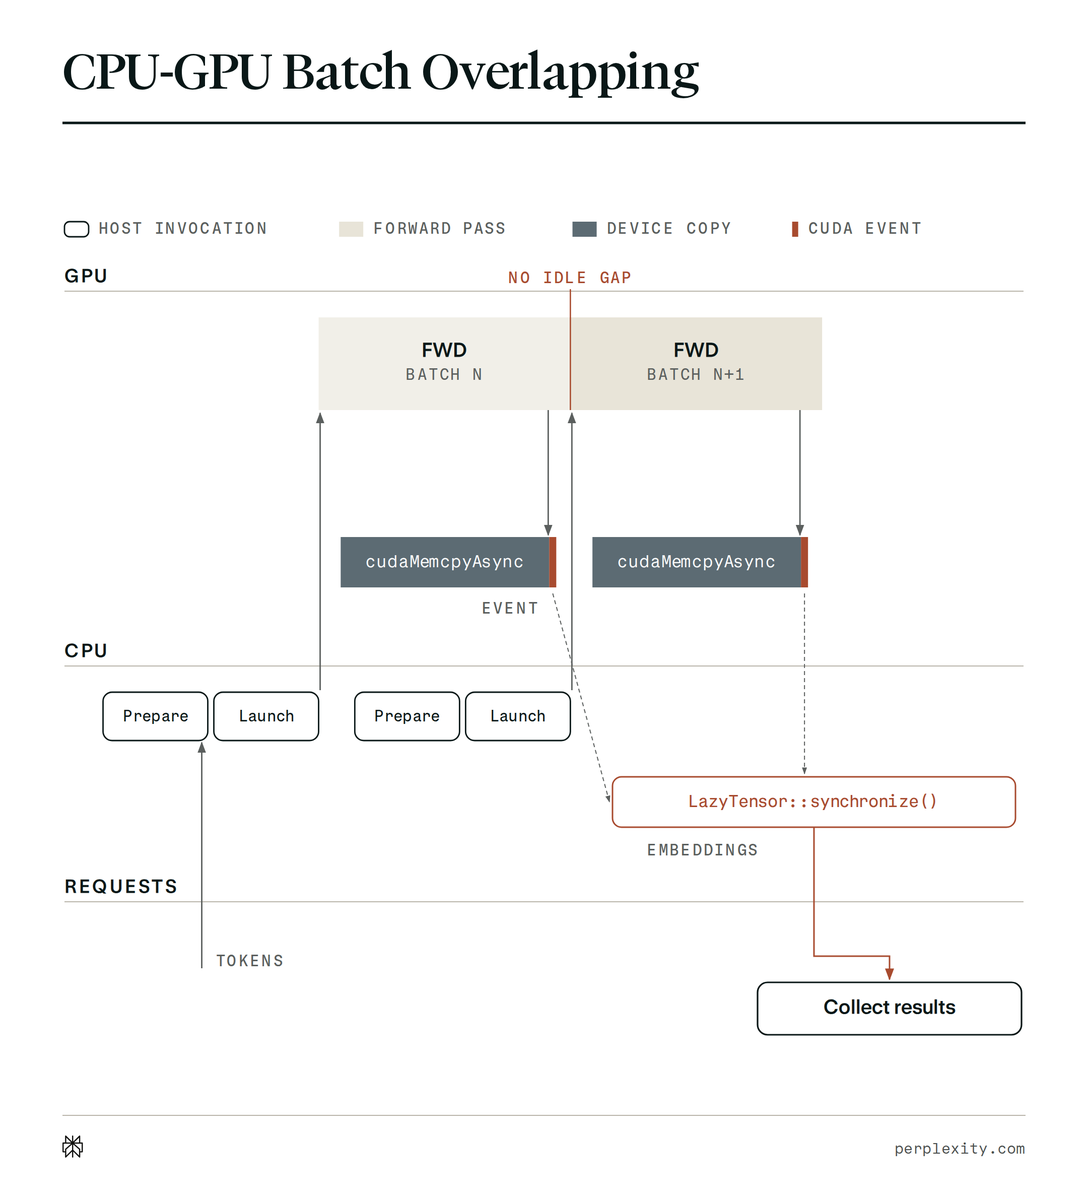
Tulip 使用两种技术来降低延迟并提高吞吐量:CUDA graphs 预记录 GPU 工作,使其一次调用即可启动,减少 CPU 开销;LazyTensors 异步跟踪结果,让 CPU 在 GPU 完成当前批次时准备下一批次。

AI推荐理由 CUDA graphs 和 LazyTensors 是实用的性能优化技术,AI 从业者可直接借鉴这些方法提升自家模型的 serving 效率,降低运营成本。

84 浏览 1,282 点赞 13 评论 1 转发 1

正文

Tulip使用两种技术来降低延迟并提高吞吐量。 CUDA图预先记录GPU工作,以便在一次调用中启动,减少CPU开销。 LazyTensors异步跟踪结果,让CPU在GPU完成当前批次的同时准备下一批次。 ![推文图片](https://pbs.twimg.com/media/HRZvA7rbEAAuwqJ.png)
查看原文(中文正文为 AI 翻译)
Tulip uses two techniques to lower latency and boost throughput. CUDA graphs pre‑record GPU work so it launches in one call, reducing CPU overhead. LazyTensors tracks results asynchronously, letting the CPU prep the next batch while the GPU finishes the current one. ![Tweet Image](https://pbs.twimg.com/media/HRZvA7rbEAAuwqJ.png)

来源报道 · 1 篇 · 以下链接均前往原始媒体

Perplexity(@perplexity_ai) Perplexity 公开搜索排序模型的 GPU serving 研究 09-05 · 原文发布
← 返回精选动态 原文

更多内容