开源工具
x.com ·
@shao__meng
webAI 发布 TwIL-LM3-Pro:3.66B 形式逻辑推理模型,支持 GGUF 本地运行
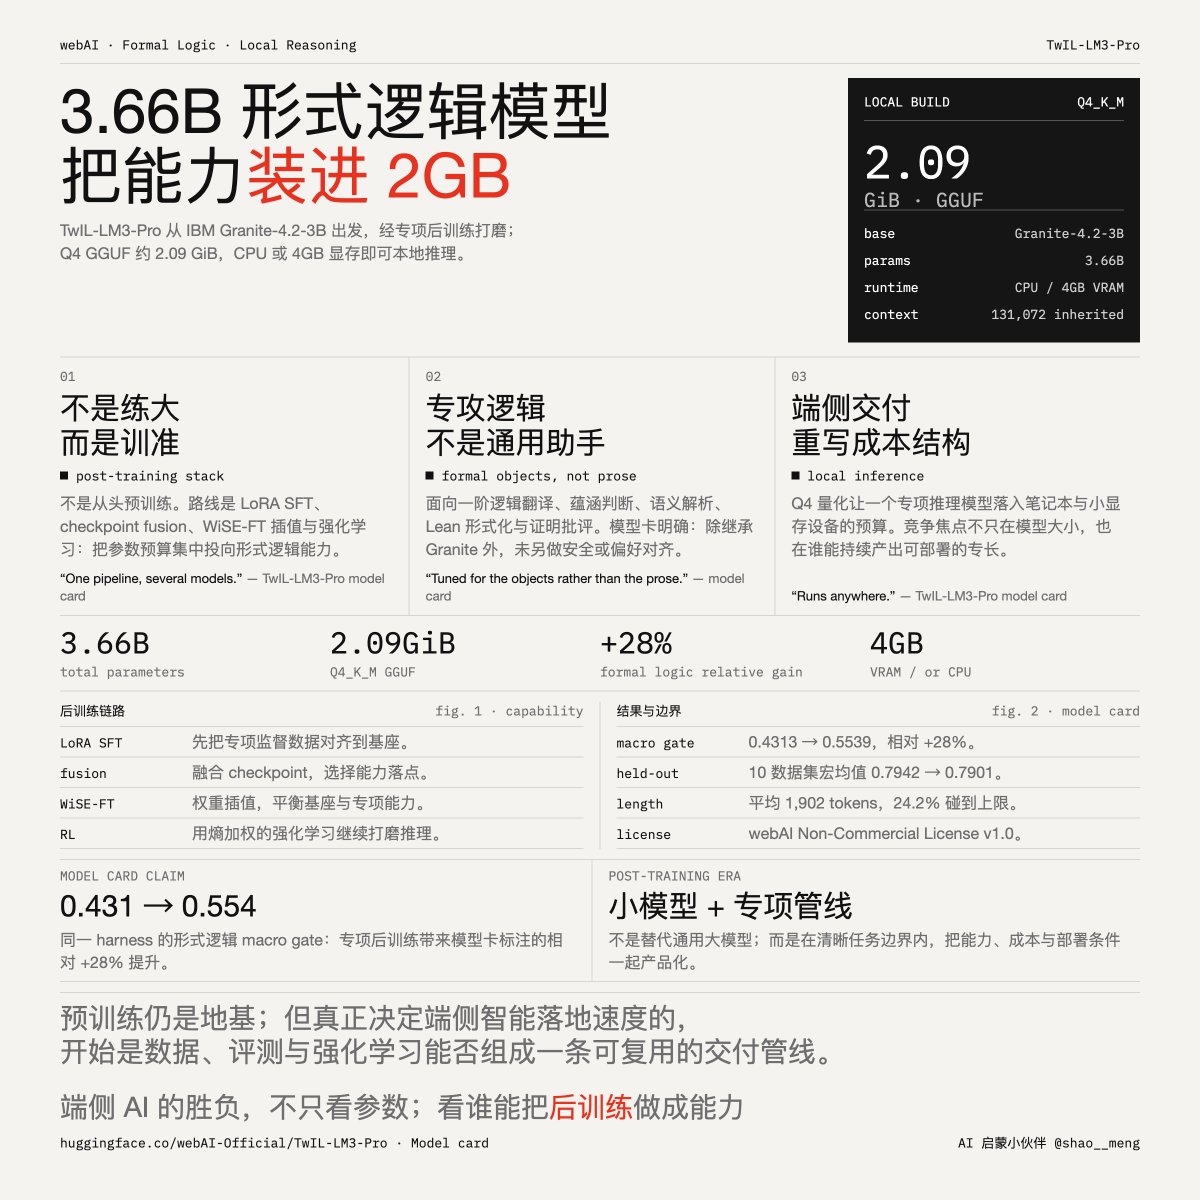
webAI 发布 TwIL-LM3-Pro,一个 3.66B 参数的推理模型,主打形式逻辑,提供 GGUF 量化版本,Q4 量化后约 2GB,可在 4GB 显存或纯 CPU 上本地运行。该模型基于 IBM Granite-4.2-3B,经 LoRA 微调、checkpoint 融合、WiSE-FT 插值和熵加权 GRPO 强化学习等后训练技术构建。webAI 称其在形式逻辑、SVAMP、MuSR 和 BIG-Bench Hard 逻辑子集上取得小模型中的较高分数,但相关对比数据来自厂商自评,尚待第三方验证。模型已在 Hugging Face 开源。
AI推荐理由 转述 webAI 发布 TwIL-LM3-Pro 3.66B 推理模型,给出基于 IBM Granite-4.2-3B、LoRA 微调、WiSE-FT 插值和熵加权 GRPO 的后训练管线,以及 GGUF Q4 约 2GB、4GB 显存或纯 CPU 可本地运行等具体信息,并附 Hugging Face 开源链接,对端侧小模型与后训练方向有参考价值。但正文为二手转述,形式逻辑、SVAMP、MuSR、BIG-Bench Hard 等对比分数均来自厂商自评,缺少第三方复现,且未提供模型卡细节,需保留不确定性。
62
浏览 615
点赞 4
评论 1
转发 0
正文
webAI [@thewebAI](https://x.com/thewebAI) 发布 TwIL-LM3-Pro:一个 3.66B 参数的推理模型,主打形式逻辑(formal logic),提供 GGUF 量化版本,Q4 量化后仅约 2GB,4GB 显存或纯 CPU 即可本地运行
TwIL-LM3-Pro 基于 IBM Granite-4.2-3B,通过 LoRA 微调、checkpoint 融合、WiSE-FT 插值和熵加权 GRPO 强化学习等一系列后训练技术打造而成。
webAI 认为:AI 正进入后训练时代。优势将属于拥有最好后训练管线、能高效产出个性化端侧智能的公司。这一点和行业趋势确实是一致的:预训练的边际收益递减,价值重心转向 RL/后训练管线、蒸馏与端侧部署。
开源模型在这:
[huggingface.co/webAI-Official…](https://huggingface.co/webAI-Official/TwIL-LM3-Pro)

David Stout@Davidstout
Half a million downloads in a month. Today, our open source family takes another step forward.
Thank you for the incredible support behind our first-generation models. We’re excited to introduce TwIL-LM3-Pro.
At just 3.6 billion parameters, it brings powerful reasoning to everyday computers, with quantized builds that run locally. No cloud required.
In our evaluation:
Formal logic: Highest recorded headline score among the small models compared—beating China’s VibeThinker-3B by 35% and Qwen3.5-4B by 24%, and Liquid AI’s LFM2.5-8B-A1B by 47%.
Broader reasoning: 95% on SVAMP and 64.1% on MuSR, the highest recorded scores among the small models compared.
BIG-Bench Hard’s logic subset: 95.4%, compared with VibeThinker-3B’s 61.1%.
We believe AI is entering a post-training era. The advantage will increasingly belong to companies with the best pipelines and those that can produce capable, personalized intelligence faster and more efficiently, then put it on devices people already own.
That’s what we’re building at webAI. And we’re only beginning to share what’s coming out of our lab.
Coming soon: Meridian, our family of frontier-class models built to run on device. Our most advanced models will be available through the [@thewebAI](https://x.com/thewebAI) application.
Join the waitlist as we expand access. Proudly built in Austin, Texas. 🇺🇸

[🔗 View Quoted Tweet](https://x.com/Davidstout/status/2105367134876365135)