大模型
website ·
[持续跟踪] Gemini 3.8 Flash遭独立评测质疑,ParseBench成绩未超上代
Gemini 3.8 Flash在ParseBench上的表现与3.7和3.6 Flash相似,在表格和内容忠实度上略好,但在图表和语义格式上稍差。独立评测者指出该版本可能过度拟合公开基准,在隐藏问题上表现更差,并出现数据回归。
AI推荐理由 该评测结果提醒AI从业者关注模型在真实文档解析任务上的表现,避免过度依赖公开基准,对模型选型有参考价值。
76
浏览 8,906
点赞 46
评论 12
转发 3
正文
Gemini 3.8 Flash 在其他基准测试中可能已经达到极限,但在文档解析方面并非如此。
我们在 ParseBench 上对其进行了基准测试。与 Gemini 3.7 Flash 相比,它在表格和内容忠实度方面表现稍好,但在图表和语义格式方面稍差。总体得分与 3.7 和 3.6 Flash 相似。
我们确实需要将基准测试向更高难度的文档发展。与此同时,解析现实世界的文档仍然是前沿模型面临的真正挑战!


Bindu Reddy@bindureddy
🚨 Gemini 3.8 Flash 在基准测试中达到极限,并且相对于 3.7 Flash 是回归 🫢
- 在我们的基准测试中,3.8 比 3.7 差
- 这个版本似乎过度拟合了公开基准测试
在我们的隐藏问题上表现更差,并且在数据分析方面有所退步。
编辑 - 话虽如此,Gemini Flash 3.7 是一个很棒的模式。Google 应该停止发布更多 Flash 版本,直接推出 Gemini 4.0
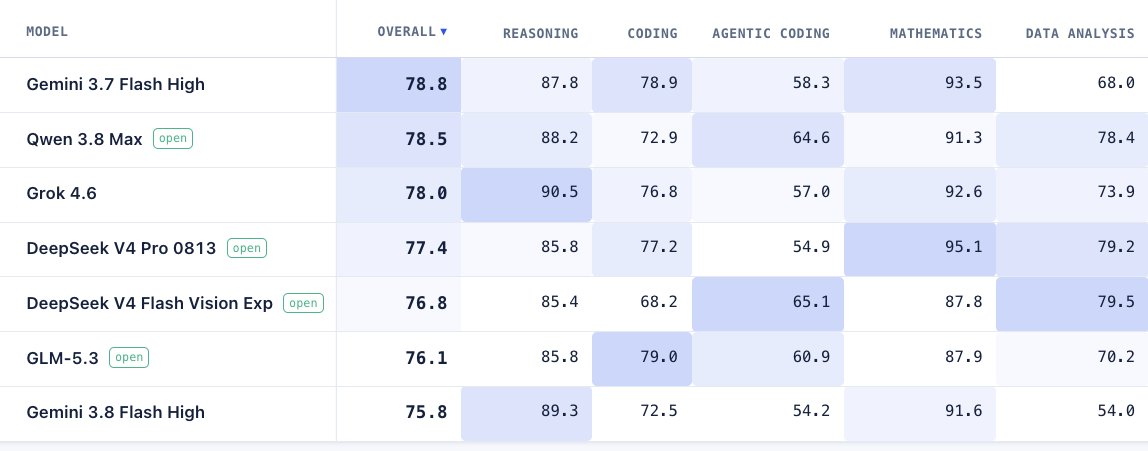
[🔗 查看引用的推文](https://x.com/bindureddy/status/2095253066023112817)
查看原文(中文正文为 AI 翻译)
Gemini 3.8 Flash might be maxxed on other benchmarks, but not quite on document parsing.
We benchmarked it on ParseBench. It does slightly better on tables + content faithfulness compared to Gemini 3.7 Flash, but a little worse on charts and semantic formatting. The overall scores are similar to those of 3.7 and 3.6 Flash.
We definitely need to evolve the benchmark towards higher difficulty documents. In the meantime though, parsing real-world docs remains a real challenge for frontier models!


Bindu Reddy@bindureddy
🚨 Gemini 3.8 Flash Is Bench Maxxed And Is A Regression on 3.7 Flash 🫢
- 3.8 is worse on our benchmark than 3.7
- This version appears to be overfit to public benchmarks
It does worse on our hidden questions and regresses in data analysis.
Edit - That said, Gemini Flash 3.7 is an AWESOME model. Google should stop with more Flash releases and drop Gemini 4.0

[🔗 View Quoted Tweet](https://x.com/bindureddy/status/2095253066023112817)