智能体
x.com ·
@omarsar0
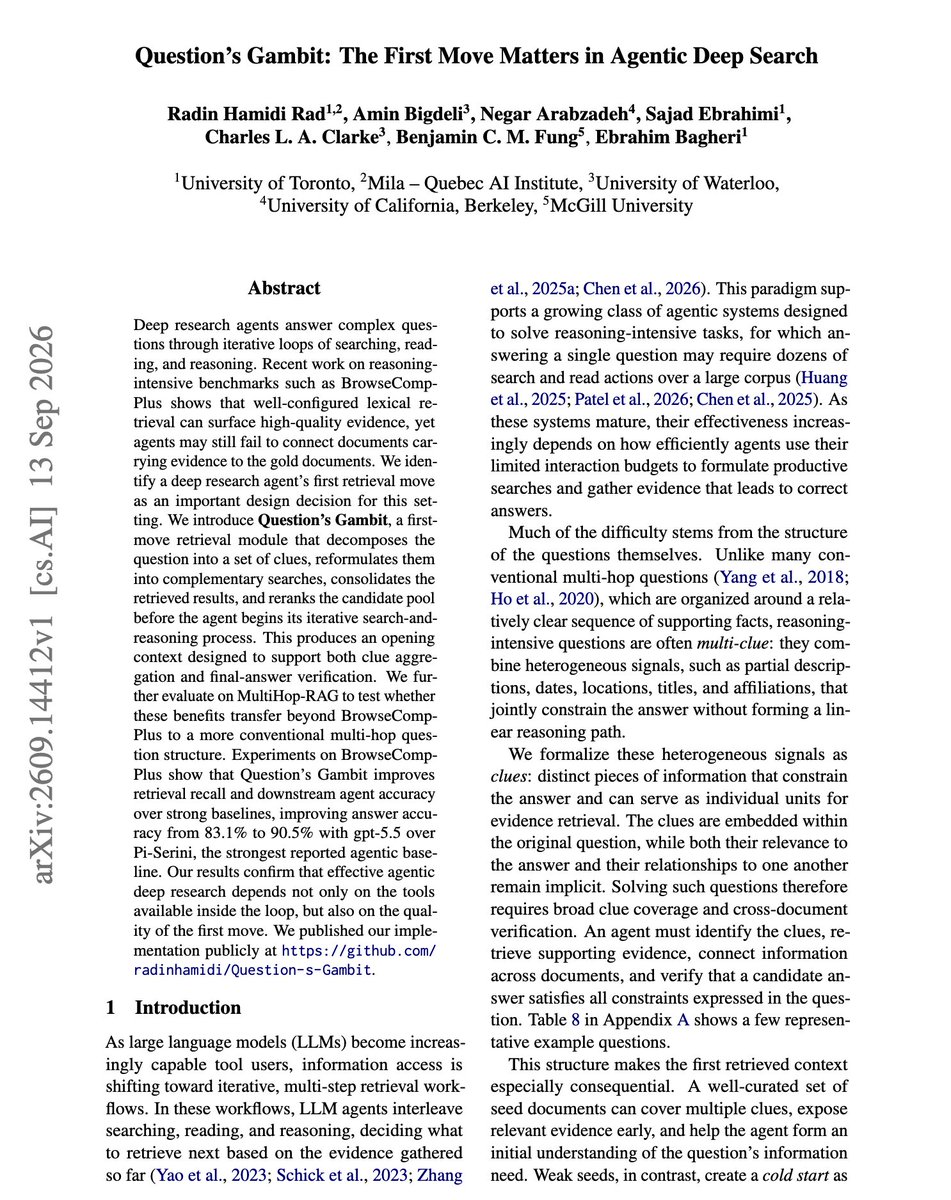
论文提出 Question's Gambit:优化深度研究 agent 的首轮检索可显著提升准确率
一条 X 帖文介绍 arXiv 论文 2609.14412 的方法 Question's Gambit:在 agent 开始搜索前,先将问题拆分为线索、把每条线索转为互补检索、汇总并重排结果,作为初始上下文注入 agent 循环。据帖文,在相同检索器与 agent 循环下,GPT-5.5 在 BrowseComp-Plus 上从 83.1% 提升至 90.5%,GPT-5.4-mini 从 68.1% 升至 79.0%,DeepSeek-v4-pro 从 71.4% 升至 76.9%,GPT-5.5 校准误差约减半,代价是每题多 2.3–5.3 次工具调用。错误分析显示 79 个剩余 GPT-5.5 错误中仅 3 个因金标文档未被检索到,其余发生在证据预览、打开或使用阶段。
AI推荐理由 转述一篇 arXiv 论文(2609.14412)提出的 Question's Gambit 方法:在 agent 检索循环开始前先拆分问题线索、生成互补检索并重排,作为初始上下文。给出具体基准数字(GPT-5.5 在 BrowseComp-Plus 上 83.1%→90.5%,GPT-5.4-mini 68.1%→79.0%,DeepSeek-v4-pro 71.4%→76.9%,校准误差约减半,每问多 2.3–5.3 次工具调用)及错误分析(79 个剩余错误中仅 3 个源于未检索到金标文档)。数据具体、有论文链接,但为二手转述,未独立验证,模型版本名称需以论文为准。
78
浏览 980
点赞 2
评论 3
转发 0
正文
Impressive paper showing how much the first retrieval step matters for deep research agents.
It helps to improve GPT-5.5 from 83.1% to 90.5% on BrowseComp-Plus with the same retriever and the same agent loop.
It seems that the gain comes from the opening context.
The authors propose Question's Gambit which runs once, before the agent starts searching.
It splits the question into clues, turns each clue into complementary searches, pools the results, and reranks them.
The agent then starts its loop with that ranked set already in context.
The same change lifts GPT-5.4-mini from 68.1% to 79.0% and DeepSeek-v4-pro from 71.4% to 76.9%, and roughly halves calibration error for GPT-5.5. It costs between 2.3 and 5.3 extra tool calls per question.
In an error analysis, only 3 of the 79 remaining GPT-5.5 errors come from the gold document never being retrieved. The other 76 happen later, when the agent previews, opens or uses the evidence.
Paper: [arxiv.org/abs/2609.14412](https://arxiv.org/abs/2609.14412)
Chat with Paper: [academy.dair.ai/papers/questio…](https://academy.dair.ai/papers/questions-gambit-the-first-move-matters-in-agentic-deep-search-2609.14412)