智能体
x.com ·
@GaryMarcus
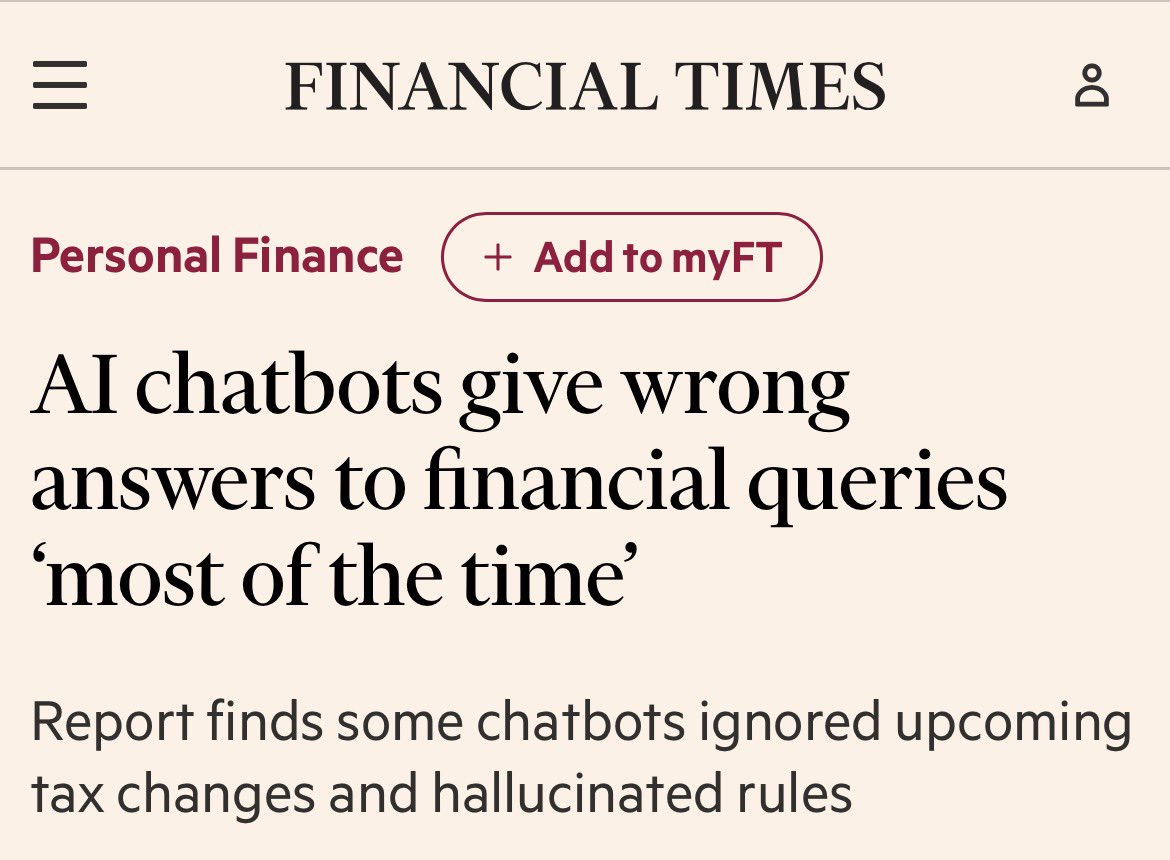
研究称主流 AI 模型金融查询错误率达 57%
Gary Marcus 转引 FT 报道,技术公司 Saturn 的研究显示 ChatGPT、Claude、Copilot、Grok 和 Gemini 在金融类查询中平均 57% 给出错误答案。该结论来自第三方研究转述,具体测试方法与样本未在帖文中说明。
AI推荐理由 转引 FT 报道中 Saturn 的研究结论:ChatGPT、Claude、Copilot、Grok、Gemini 在金融查询上平均 57% 给出错误答案。涉及主流模型可靠性,有具体数字与媒体来源,但为转述且未提供研究方法细节,需保留不确定性。
62
浏览 3,156
点赞 19
评论 0
转发 5
正文
AGI FTW @ FT

Kalani o Māui@MauiBoyMacro
“The most popular AI models from ChatGPT, Claude, Copilot, Grok and Gemini provided wrong answers to financial queries 57 per cent of the time on average, according to research from technology firm Saturn.” 👇🏼[ft.com/content/c0cd35…](https://www.ft.com/content/c0cd359d-df84-4208-a789-ffa864b43666)7J
[🔗 View Quoted Tweet](https://x.com/MauiBoyMacro/status/2101314875914059905)