智能体
x.com ·
@mem0ai
mem0 发布 DolphinBench:将 Agent 记忆的准确率、成本与延迟放在同一榜单
mem0 发布 DolphinBench,指出编码、工具调用和长上下文检索已有成熟基准,而记忆评测多停留在问答式打分。该基准在长历史后对动作评分,并把准确率、成本与延迟纳入同一榜单,以回答选型时的成本与延迟问题。
AI推荐理由 mem0 正式发布 DolphinBench,针对现有记忆评测多为问答式、且忽略成本与延迟的问题,提出在长历史后对动作评分,并将准确率、成本、延迟放在同一榜单。问题定义清晰,对 Agent 记忆系统选型有实际参考价值,但效果仍需看论文与榜单数据。
66
浏览 2,117
点赞 29
评论 3
转发 4
正文
Today we are releasing DolphinBench: Mapping the Pareto frontier of agent memory.
Coding, tool use, and long-context retrieval already have strong public benchmarks. Memory still mostly gets graded as a quiz: ask a question, judge the answer, maybe report precision and recall.
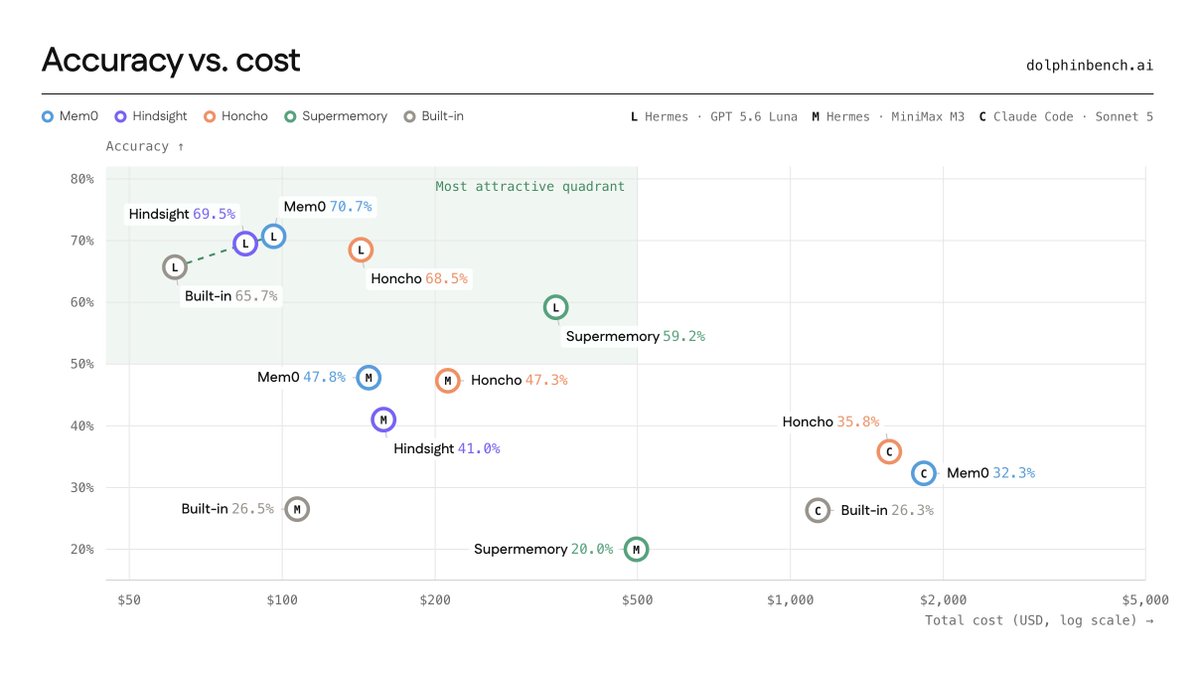
DolphinBench grades that action after long history, and puts accuracy, cost, and latency on one board.
[dolphinbench.ai](https://dolphinbench.ai/)

Deshraj Yadav@deshrajdry
Today we are releasing DolphinBench: Mapping the Pareto frontier of agent memory.
Coding, tool use, and long-context retrieval already have strong public benchmarks. Memory still mostly gets graded as a quiz: ask a question, judge the answer, maybe report precision and recall.
A lot of those boards are getting saturated. They also skip the two questions that matter when you pick a memory system to ship:
At what cost?
At what latency?
Agents are not taking memory quizzes but they take actions. The fact that matters is usually missing from the request. Either it shows up in the tool call, or the agent does the wrong thing while sounding fluent.
DolphinBench grades that action after long history, and puts accuracy, cost, and latency on one board.
[dolphinbench.ai](http://dolphinbench.ai)

[🔗 View Quoted Tweet](https://x.com/deshrajdry/status/2102435297887911969)