大模型
x.com ·
@FinanceYF5
AI 制药正成为“瓶颈交易”:上游实验验证需求被 AI 放大
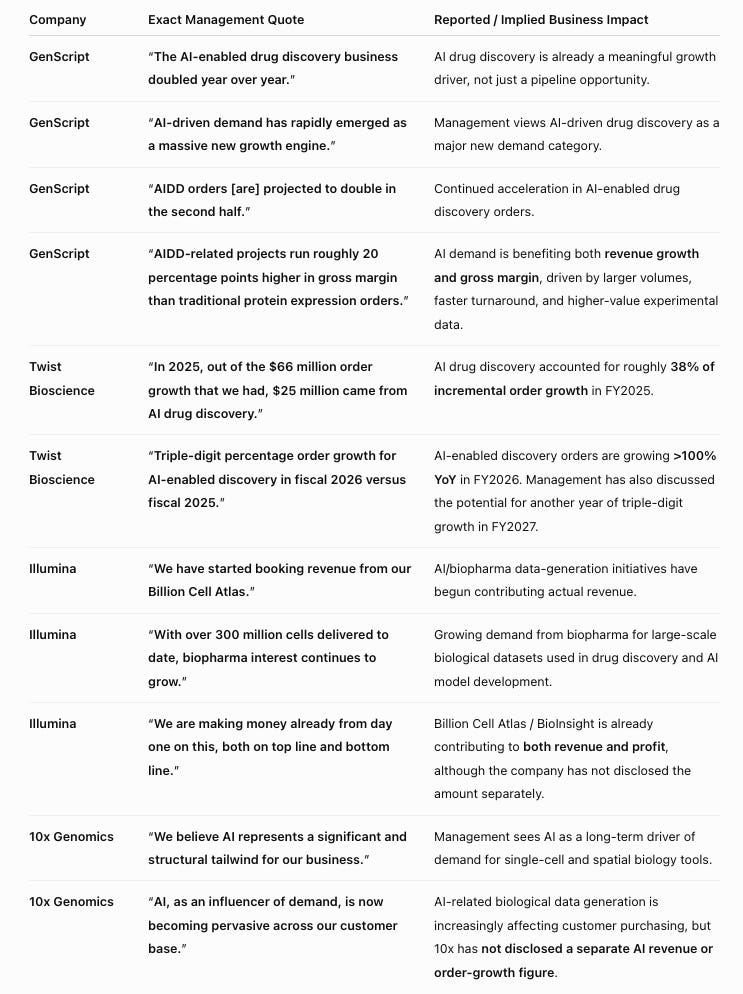
Freda Duan 认为 AI 药物发现正经历真正的范式转变:前沿 AI 实验室大举进入,供应链从 DNA、蛋白、检测、测序、自动化到临床前测试开始承压。TWST 预计 FY26 AI 赋能药物发现订单三位数增长,FY27 再翻倍;GenScript AIDD 业务 1H26 同比翻倍,平台宣称每日可验证 4000+ 设计,渠道调研称实际约 8000/日、年底或达 16000/日。AI 让假设生成近乎免费,瓶颈转向湿实验验证;Anthropic Claude 设计 1320 个蛋白结合体仅 354 个成功结合,失败样本可作为负标签训练下一代模型。
AI推荐理由 转述 Freda Duan 关于 AI 制药(AIDD)成为“瓶颈交易”的分析,给出具体供应链环节(DNA→蛋白→检测→测序→自动化→临床前)与公司(TWST、GenScript、ILMN、TXG、CRO),并引用 TWST FY26/FY27 三位数订单增长预期、GenScript AIDD 业务 1H26 同比翻倍及 4000+/日设计验证能力等可核查线索;Anthropic Claude 设计 1320 个蛋白结合体、仅 354 个成功结合的案例说明失败数据仍有训练价值。局限:属二手转述与渠道调研(channel checks),8000/日、16000/日等数字为未证实估计,需以公司披露为准。
72
浏览 341
点赞 0
评论 1
转发 0
正文
阅读原文:
[x.com/FredaDuan/stat…](https://x.com/FredaDuan/status/2106851949400469887)

Freda Duan@FredaDuan
AI Drug Discovery Is Becoming a Bottleneck Trade
I get excited when an industry starts going through a real regime change. AI drug discovery (“AIDD”) increasingly looks like one of those moments.
Two things are happening:
1/ Upstream: the frontier AI labs are piling in.
2/ Downstream: The supply chain is clearly moving.
Supply-chain checks suggest the upstream picks-and-shovels of discovery and early preclinical R&D are starting to feel the increase in experimental volume.
DNA → protein → assays → sequencing → automation → preclinical testing
Names across that stack include $TWST , [@GenScript](https://x.com/GenScript) , $ILMN , $TXG , lab-automation vendors and CROs.
$TWST expects triple-digit percentage growth in AI-enabled drug-discovery orders in FY26, and another year of triple-digit order growth in FY27.
[@GenScript](https://x.com/GenScript)'s AIDD business doubled YoY in 1H26. Its current platform advertises industrial-scale validation of 4,000+ designs/day, with integrated sequence-to-data workflows. Our channel checks suggest the ramp is moving even faster: roughly 8,000 designs/day currently, with a path toward ~16,000/day by YE26.
---
Why does AI drive more wet-lab demand?
1/ AI makes hypothesis generation almost free → way more shots on goal.
The bottleneck is moving from expert-driven design to biological validation.
2/ AI models need continuous experimental feedback — and both good and bad data are useful.
Traditionally, only the highest-conviction A+ candidates might get pushed into expensive validation. With AI, even the B/C candidates can be valuable because failed experiments generate training data.
[@GenScript](https://x.com/GenScript) has said its sequence-to-binding workflow can return data in 4–7 days, and that faster cycle times matter because AI models depend on continuous experimental feedback.
[@Anthropic](https://x.com/Anthropic) is a clean example. [@claudeai](https://x.com/claudeai) designed 1,320 protein binders. [@adaptyvbio](https://x.com/adaptyvbio) converted those digital sequences into DNA, expressed the proteins and tested binding. Only 354 actually bound. And the 966 failures are not wasted. They are useful negative labels: what does not express, what does not bind, what has poor affinity. Those results help train the next model iteration.
3/ Wet labs are no longer just making drugs. They are making training data.
$TWST / [@GenScript](https://x.com/GenScript) increasingly look like biological data foundries.
$TWST explicitly talks about generating model-ready data from AI-designed sequences. In some workflows, the customer may care less about receiving the physical protein than about getting structured experimental results back into the model.
Traditional drug discovery asks: “Does candidate X work?”
AI drug discovery also asks: “What can this experiment teach the model?”
---
TAM of AIDD
If AI is simply a better R&D tool, the relevant spending pool is the $300–400B of annual global pharma R&D. If AI meaningfully increases the number of viable drug programs, the opportunity is larger because it expands downstream demand for DNA synthesis, protein production, assays, and preclinical work.
Near term, we can also size demand from AI-company spending. If Anthropic reaches $80B of ARR in 2026 and spends just 1% on AIDD, that alone would imply ~$800M of annual investment.
---
Trade setup
This is a trade that could have long legs. It’s hard to really stop working until PhaseI/II results (2028+)
It smells a lot like the bottleneck trade we just saw in semis: GPUs → HBM → networking → power/cooling. In biology, It basically follows the drug discovery process downstream: AI models → designs → DNA/protein → assays → preclinical capacity.
After the upstream picks-and-shovels, animal testing could become the next bottleneck. Monkey prices are already near prior highs and CRO capacity is tight. AIDD pushing more candidates into preclinical development would only add demand.
?? But clinical trials are still the bottleneck?
This is the biggest pushback I keep coming back to. No matter how fast discovery becomes, drugs still need to go through preclinical → Phase I → Phase II → Phase III → approval. You still need patients, time and capital.
But that doesn’t mean the bottleneck trade won’t work. More viable candidates — especially with higher success rates — still means more demand throughout the development process.
And who knows: clinical trials themselves may eventually be optimized by AI.
?? What breaks the trade?
Near term, the picks-and-shovels trade breaks if experimental budgets stop growing, AI-generated designs don’t translate into useful wet-lab hits, or capacity catches up too quickly.
Longer term, the thesis breaks if AI drugs look great in discovery / Phase I but fail at normal rates in Phase II/III. That is why Phase II matters so much.
?? Milestones
Late 2026–2027: first Isomorphic-designed drugs enter human trials; more AI-native programs move into IND-enabling work / tox.
2028–2030: clinical trial results start telling us whether AI-designed drugs actually perform better than conventional drugs.
Calling all the "bottleneck bros". :) [@jukan05](https://x.com/jukan05)[@zephyr\_z9](https://x.com/zephyr_z9)[@aleabitoreddit](https://x.com/aleabitoreddit)[@ParadisLabs](https://x.com/ParadisLabs)
+++
More comprehensive analysis: [robonomics.substack.com/p/ai-drug-disc…](https://robonomics.substack.com/p/ai-drug-discovery-is-becoming-a-bottleneck?r=3hcp4&utm_campaign=post-expanded-share&utm_medium=web)
[🔗 View Quoted Tweet](https://x.com/FredaDuan/status/2106851949400469887)