智能体
x.com ·
@omarsar0
NVIDIA 论文:为全双工语音模型引入工具调用
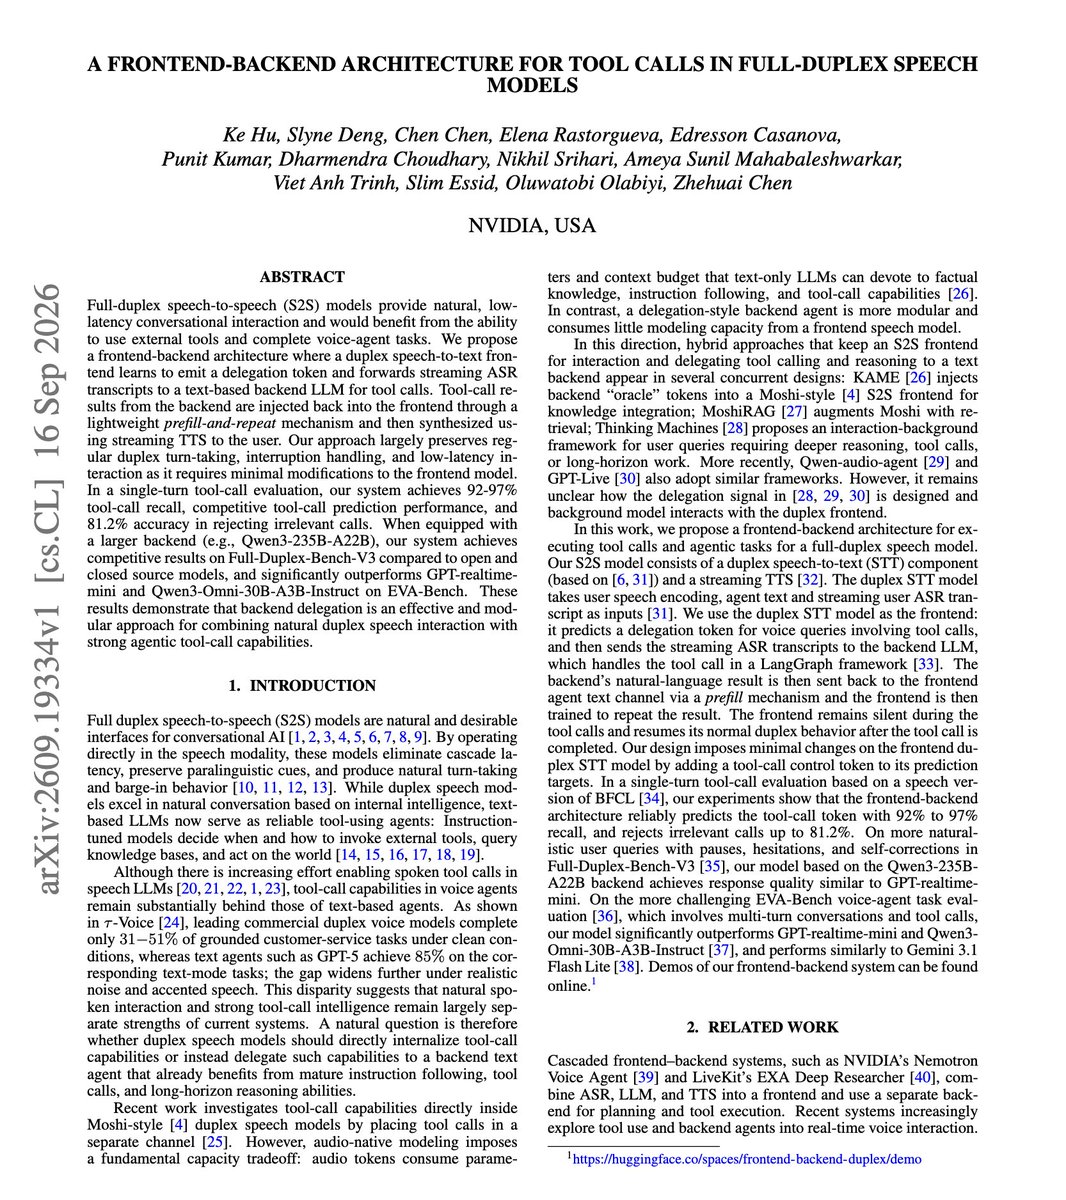
一篇 NVIDIA 论文提出前后端架构,让全双工语音模型具备工具调用能力:双工前端学习发出 delegation token,将流式转写交给文本后端 LLM 执行工具调用,再通过轻量 prefill-and-repeat 机制回传结果并由流式 TTS 播报。推文称工具调用召回率为 92.0–97.2%,拒绝无关调用准确率 81.2%,轮次切换、流式 ASR 词错率和口语智能保持无工具调用时的基线水平;并对比商业双工语音模型在客服任务上完成率 31–51%,而 GPT-5 等文本 Agent 在文本模式下可达 85%。论文编号 arXiv:2609.19334。
AI推荐理由 介绍 NVIDIA 一篇关于全双工语音模型工具调用的论文,给出具体架构思路(前端发出 delegation token、转交文本后端 LLM 执行工具调用、再经 prefill-and-repeat 回传并由 TTS 播报)及量化结果:工具调用召回率 92.0–97.2%、拒绝无关调用准确率 81.2%,并对比商业双工语音模型在客服任务上 31–51% 与文本 Agent 85% 的差距。有 arXiv 编号可查,信息密度高,对语音 Agent 落地有参考价值;但数据来自推文转述,未独立核验,且属预印本。
78
浏览 2,596
点赞 16
评论 8
转发 1
正文
NVIDIA research papers are on fire recently!
Here is another interesting paper where they give full-duplex speech models tool calls.
(bookmark it)
Commercial duplex voice models complete 31 to 51 percent of grounded customer-service tasks under clean conditions.
Text agents like GPT-5 reach 85 percent on the same tasks in text mode.
Most of what a voice agent loses, it loses in the speech pipeline.
The fix routes the decision out of the speech model.
The duplex frontend learns to emit a delegation token, forwards streaming transcripts to a text backend LLM for the tool call, and receives the result through a lightweight prefill-and-repeat mechanism before streaming TTS speaks it.
Tool-call recall runs 92.0 to 97.2 percent with 81.2 percent accuracy at rejecting irrelevant calls. Turn-taking rate, streaming ASR word error rate and spoken-language intelligence all stay at the no-tool-call baseline.
Paper: [arxiv.org/abs/2609.19334](https://arxiv.org/abs/2609.19334)
Chat with Paper: [academy.dair.ai/papers/a-front…](https://academy.dair.ai/papers/a-frontend-backend-architecture-for-tool-calls-in-full-duplex-speech-models-2609.19334)