智能体
x.com ·
@omarsar0
Meta 论文提出 Sharpening Tax:后训练削弱测试时可扩展性,PTGS 可缓解
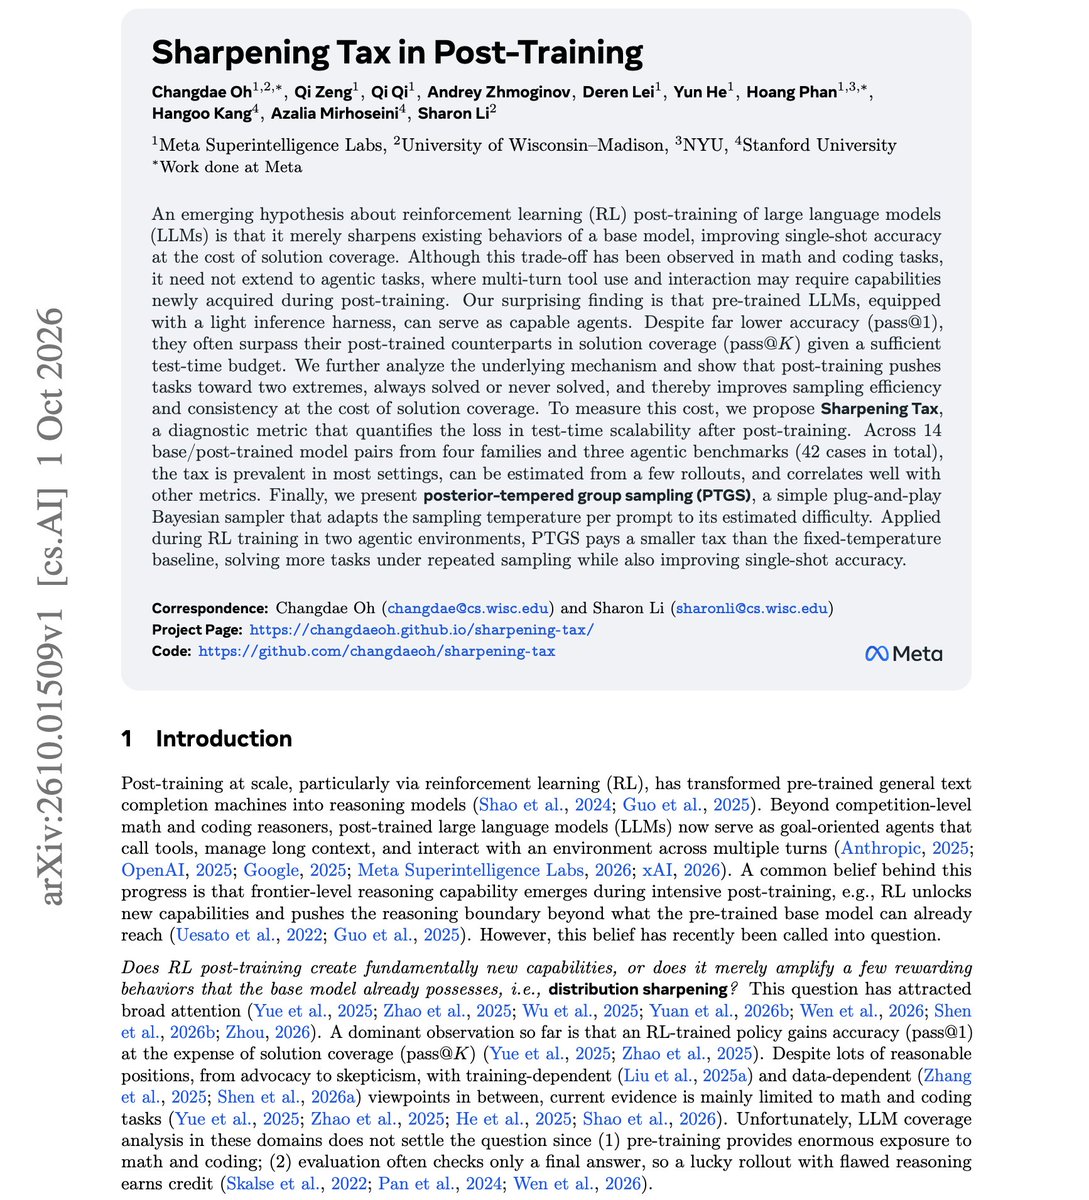
该帖转述 Meta Superintelligence Labs 的论文发现:配备轻量推理 harness 的预训练基座模型在测试时预算充足时,可在 BFCL v4 多轮、ACEBench、WebShop 等任务上解决更多 agentic 任务,甚至超过 RL 后训练版本;后训练模型在 pass@1 上占优,但一致性上升、覆盖率下降,作者称之为 Sharpening Tax,在 42 组基座/后训练模型对比中多数出现且随模型规模增大。其修复方法 PTGS 在 RL 中按估计难度为每个 prompt 设置采样温度,可降低该税并提升 pass@1。
AI推荐理由 转述 Meta Superintelligence Labs 论文的核心发现:预训练基座模型配轻量推理 harness 在充足测试时预算下可超越 RL 后训练版本,并提出 Sharpening Tax 概念与 PTGS 修复方法,涉及 BFCL v4、ACEBench、WebShop 等基准,对预训练/后训练研究有具体参考价值;但为二手转述,具体数据需查原文核实。
78
浏览 3,432
点赞 43
评论 12
转发 2
正文
Great paper for all you pre-training and post-training nerds. The surprising finding is that pre-trained LLMs, equipped with a light inference harness, can serve as capable agents and can even surpass post-trained counterparts with a sufficient test-time budget.

DAIR.AI@dair\_ai
Banger paper from Meta Superintelligence Labs.
They find something super interesting and unexpected.
(bookmark it)
Base models with a light harness often solve more agentic tasks than their RL post-trained versions when both get enough samples.
Post-trained models win on pass[@1](https://x.com/1). At large K, base models frequently solve tasks the post-trained ones never solve on BFCL v4 multi-turn, ACEBench, and WebShop.
This is because post-training pushes each task toward always solved or never solved. Consistency goes up, and coverage goes down.
The authors call the lost test-time scalability the Sharpening Tax. Across 42 base and post-trained pairs, it shows up in most settings, grows with model size, and can be estimated from a few rollouts.
Their fix, PTGS, sets the sampling temperature per prompt from its estimated difficulty during RL. It pays a smaller tax and also raises pass[@1](https://x.com/1).
Paper: [academy.dair.ai/papers/sharpen…](https://academy.dair.ai/papers/sharpening-tax-in-post-training-2610.01509)
[🔗 View Quoted Tweet](https://x.com/dair_ai/status/2106418508259377411)