大模型
website ·
LlamaIndex发布Extract Turbo:文档抽取提速3至5倍
LlamaIndex发布Extract Turbo,这是最快的VLM驱动的文档抽取解决方案,比同类OCR方案快3-5倍,精度相当或更高。它并行处理页面,中位延迟每页3.7秒,且延迟不随文档大小增加。
AI推荐理由 文档抽取速度的大幅提升可显著提高AI数据处理效率,对依赖文档解析的AI应用开发者有直接帮助。
89
浏览 11,639
点赞 97
评论 5
转发 20
正文
今天,我们激动地推出Extract Turbo ⚡️——最快的基于VLM的文档提取解决方案。
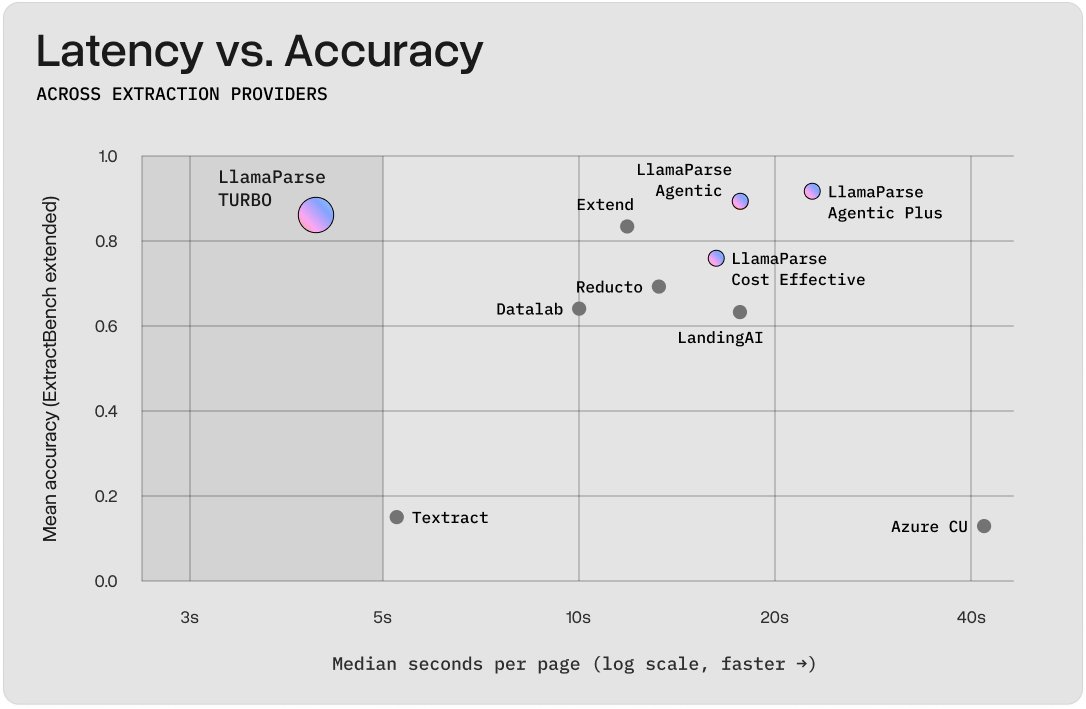
它比所有其他同类OCR解决方案(包括我们的其他LlamaParse层级)快3-5倍,同时精度相当或更高。

LlamaIndex 🦙@llama\_index
文档提取刚刚换上了新档位。⚡️
为Extract引入Turbo模式,这是我们目前从文档中提取结构化数据的最快方式。
它的运行速度大约是成本效益层的4倍,精度相当,每页中位延迟为3.7秒。Turbo并行处理页面,因此随着文档大小增加,延迟几乎保持不变。
今天开始提供测试版。
阅读完整介绍 → [llamaindex.ai/blog/introduci…](https://www.llamaindex.ai/blog/introducing-turbo-our-fastest-extraction-tier)

[🔗 查看引用的推文](https://x.com/llama_index/status/2095554829556776977)
查看原文(中文正文为 AI 翻译)
Today, we're excited to launch Extract Turbo ⚡️ - the fastest VLM-powered document extraction solution.
It is 3-5x faster than all other comparable OCR solutions, including our other LlamaParse tiers, at equivalent or higher accuracy.


LlamaIndex 🦙@llama\_index
Document extraction just got a new gear. ⚡️
Introducing Turbo mode for Extract, our fastest way yet to pull structured data from documents.
It runs roughly 4× faster than our Cost Effective Tier at comparable accuracy, with a median latency of 3.7 seconds a page. Turbo processes pages in parallel, so latency stays nearly flat as document size grows.
Available in beta today.
Read the full breakdown → [llamaindex.ai/blog/introduci…](https://www.llamaindex.ai/blog/introducing-turbo-our-fastest-extraction-tier)

[🔗 View Quoted Tweet](https://x.com/llama_index/status/2095554829556776977)