大模型
x.com ·
@shao__meng
从零构建推理模型第 6 讲:用 GRPO 实现可验证奖励强化学习
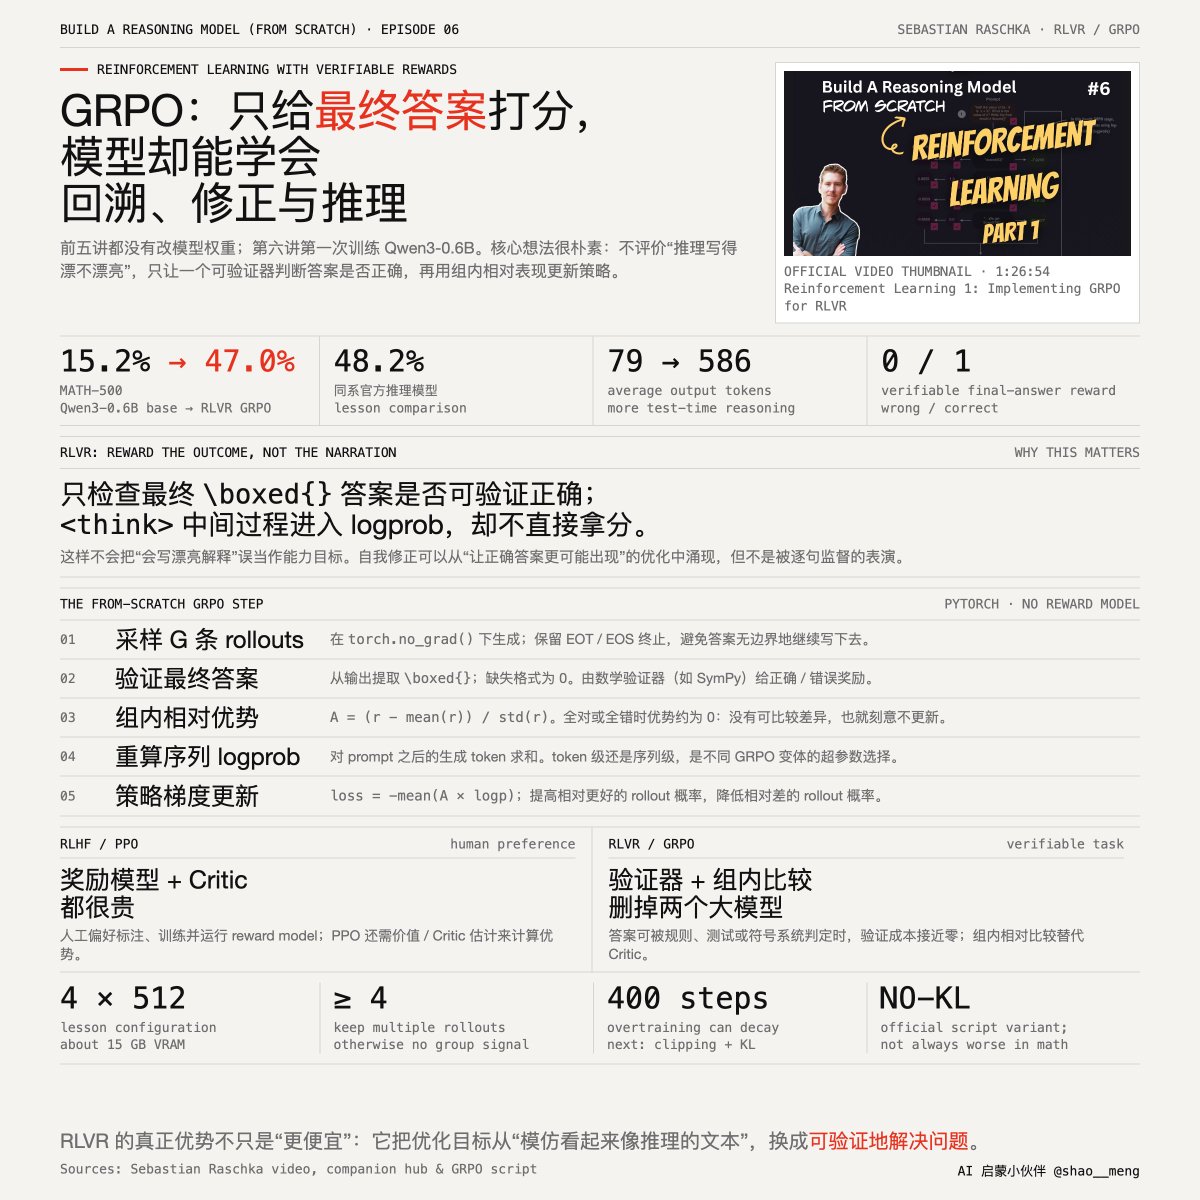
Sebastian Raschka 的「Build A Reasoning Model (From Scratch)」系列更新第 6 讲,首次真正训练模型:用纯 PyTorch 从零实现 GRPO,以 SymPy 验证器按答案对错给奖励,将 Qwen3-0.6B 在 MATH-500 上的准确率从 15.2% 提升到 47%,接近 Qwen 官方推理模型的 48.2%。帖中同时给出实现要点(采样需用 no_grad 并保留 EOT、优势按组内相对排名计算、全对全错时优势为 0)与局限(平均输出从 79 token 增至 586、约 400 步后过训性能下降、4 rollouts×512 token 约需 15GB 显存)。
AI推荐理由 该帖转述 Sebastian Raschka「Build A Reasoning Model (From Scratch)」第 6 讲,给出具体可核验的技术细节:用纯 PyTorch 从零实现 GRPO,以 SymPy 验证器提供可验证奖励,Qwen3-0.6B 在 MATH-500 上从 15.2% 提升到 47%,接近官方推理模型的 48.2%,并说明输出长度从 79 token 增至 586、过训会崩溃、4 rollouts×512 token 约需 15GB 显存等局限。内容面向开发者,信息密度高,但为对他人教程的转述,非一手发布。
82
浏览 556
点赞 2
评论 1
转发 0
正文
Build A Reasoning Model (From Scratch) 系列来到了第 6 讲「用 GRPO 做可验证奖励的强化学习」
作者 [@rasbt](https://x.com/rasbt) 前面 5 讲(推理时扩展、自一致性、自我修正)都不改模型权重,今天第一次真正训练模型:用纯 PyTorch 从零实现 GRPO 算法,把 Qwen3-0.6B 基础模型的 MATH-500 准确率从 15.2% 提升到 47%,几乎追平 Qwen 官方推理模型的 48.2%。
视频系列更新:
[youtube.com/playlist?list=…](https://www.youtube.com/playlist?list=PLfrHAQCRxtUs)
只训最终答案。RLVR 只按答案对错给奖励(对1错0), 里的中间推理只算 log 概率、不打分。一是防止模型学会写“漂亮的假推理”来应付监控,二是 R1 论文实证过程奖励无用。由此自发涌现 "aha moment":模型没被教过自我修正,却会说“等等,我算错了”然后回溯重算。强模型推理链变短不是藏思考,是不需要,如同数学专家打的草稿比新手少。
RLVR 的本质优势是删模型。RLHF(PPO)需要人工标注、训练并运行一个昂贵的奖励模型,外加一个 Critic;RLVR 用 SymPy 验证器判对错,几乎零成本。GRPO 的巧思是用组内相对比较替代 Critic,又省掉一个跟主模型一样大的模型。
算法本体(厨师类比:顾客点单=提示,多道菜=rollouts,点赞点踩=奖励,组内相对排名=优势,厨师风格=策略,老菜谱=参考模型防跑偏)。代码五步:采样 rollouts(须用 no\_grad 而非 inference\_mode,且保留 EOT 终止符防止答案越写越长)→ SymPy 判奖励(缺 \boxed{} 格式判0分)→ 算优势 (r−均值)/标准差,全对全错时为0即不学习,是刻意设计 → 算序列 log 概率(token 级 vs 序列级本质是超参数,GSPO 用后者,DAPO 用前者)→ 损失 −mean(优势×log概率),标准 PyTorch 循环训练。
结果:Qwen3-0.6B 基座从 15.2% 提到 47%,几乎追平官方推理模型的 48.2%,代价是平均输出从 79 token 涨到 586。三条教训:过训会崩(400步跌到44%,再训到30%),须靠下一讲的 clip 和 KL 修正;4 rollouts × 512 token 约需 15GB 显存,rollouts 至少保 4 个;KL 项非必需,数学模型去掉它常常反而更好。

Sebastian Raschka@rasbt
Reasoning from scratch, round number 6!
An introduction (and implementation) of Reinforcement Learning with Verifiable Rewards (RLVR) and Group Relative Policy Optimization (GRPO).
00:00 Introduction
01:54 What makes a reasoning model different?
04:25 Reasoning traces and model capability
08:29 Accuracy and format rewards
11:34 Aha moments and DeepSeek-R1 training
14:41 Reasoning effort and answer length
18:38 RLHF and RLVR
23:04 GRPO vs. PPO
26:40 GRPO explained with a cooking analogy
31:43 The KL term and simplified GRPO
35:04 Loading the pretrained model
36:07 Loading the MATH training data
39:26 Sampling model responses
46:30 Computing verifiable rewards
49:55 Computing advantages
51:54 Token and sequence log probabilities
55:29 Implementing sequence log probabilities
57:37 Fixing the inference-mode error
1:02:24 Computing the GRPO loss
1:04:37 Putting the GRPO step together
1:09:19 The GRPO training loop
1:12:57 Training settings, logging, and checkpoints
1:17:24 Running training and inspecting outputs
1:19:28 Loading and evaluating checkpoints
1:22:33 MATH-500 results and training stability
1:24:05 Memory requirements and next steps
[Your browser does not support the video tag.](https://video.twimg.com/amplify_video/2106367905952595968/vid/avc1/3840x2160/_obvT7L4XSMZxgGT.mp4?tag=29)
[🔗 View on Twitter](https://x.com/rasbt/status/2106369670680871031/video/1)
[🔗 View Quoted Tweet](https://x.com/rasbt/status/2106369670680871031)